使用 Gemini Decisions API 回答是/否、选择和评分问题
技术背景
传统做法让大模型生成 yes/no 文本或 JSON,再解析字符串,存在输出不稳定、需处理格式异常、按输出 token 计费等问题。Decisions API 把决策建模为对固定问题集的条件概率估计:一次请求对同一 input 只做一次前向计算,返回校准概率与置信度,不生成任何文本,输出 token 恒为 0。它适合请求路由、策略合规检查、工具选择、数据集打分排序、实时 UI/音视频状态判断等需要低延迟、可设阈值、可批量并行检查的场景。主要限制是仅支持 v1beta 与单一模型、问题指令仅限文本、不支持 gs:// 与 YouTube URL、无上下文缓存与 Batch API。
核心原理
核心是把问题定义为带类型的判别任务。noul 返回 P(yes) 的校准概率(限制在 0.01–0.99)与 confidence=max(p,1-p),可用 true_description/false_description 澄清边界。choice 对 2–255 个选项输出归一化概率分布与获胜项,键按 UTF-8 字节序排序,平局按字母序打破,且总会在选项间分配概率,因此需用 confidence 或配套 noul 判断是否越界。score 的 criteria 是有序文本等级列表,索引 0..N-1 自动构成数值刻度,返回各等级概率、概率加权期望 score(连续值)与 legend 映射,confidence 反映分布集中度。所有问题共享同一 input 且彼此不可见,问题键不暴露给模型,故 instructions 必须写完整问题。
架构分析
系统由三层组成:客户端层用 google-genai 3.2+ 初始化 Client 并显式指定 api_version=v1beta;请求层构造 input(文本、JSON 字符串或 Content 块列表,支持 image/audio/video/document,可传 base64 data、Files API URI 或 HTTPS uri,并用 resolution 控制 token)与 questions 映射;响应层按问题键返回类型化答案对象及 usage。设计上把共享上下文与独立判别解耦,使单次预填充可承载上千个问题,新增问题边际成本极低;把决策语义下沉到概率空间,让阈值、排序、归一化等策略留在应用代码中,便于灰度与回滚。多问题组合(noul 范围检查 + choice 路由 + score 风险)构成可解释的决策流水线。
完整实战教程
##### 版权所有 2026 Google LLC。
# @title Licensed under the Apache License, Version 2.0 (the "License");
# you may not use this file except in compliance with the License.
# You may obtain a copy of the License at
#
# https://www.apache.org/licenses/LICENSE-2.0
#
# Unless required by applicable law or agreed to in writing, software
# distributed under the License is distributed on an "AS IS" BASIS,
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
# See the License for the specific language governing permissions and
# limitations under the License.
使用 Gemini Decisions API 回答是/否、选择和评分问题
 Gemini Decision 模型(
gemini-decision-1)和 Decisions API(client.decisions / /v1beta/decisions)可在单次请求中针对你的数据回答一个或多个带类型的问题。你发送一个 input(文本、JSON、图像、音频、视频或 PDF)以及一个 questions 映射。
对于每个问题,你会得到跨各结果校准后的概率以及一个最佳答案——是/否概率(noul)、选项概率与最佳选择(choice),或概率加权的评分标准得分与等级概率(score)——外加一个 confidence 分数。由于不生成任何内容,因此没有需要解析的输出文本,也没有需要付费的输出 token(total_output_tokens = 0)。
典型用途:
* 将请求路由到某个模型、队列、智能体或工具。
* 同时依据多条策略规则检查输入和输出。
* 判断智能体需要哪些工具,或是否应压缩、升级或停止。
* 依据评分标准对大型数据集进行过滤、评分或排序。
* 实时响应 UI 状态、音频、视频帧或文档。
Decisions API 或结构化输出
| 当你需要以下内容时,使用 Decisions API(decisions.create) | 当你需要以下内容时,使用 Interactions API(interactions.create) |
| :--- | :--- |
| 是/否概率(noul)、从固定集合中选择一个选项(choice),或在固定量表上评分(score) | 生成的文本、摘要或解释 |
| 可设置阈值或排序的校准概率和 confidence 分数 | 遵循你自己的 JSON schema 的提取值或对象 |
| 在一次调用中对同一 input 进行许多独立检查 | 带参数的工具调用 |
| 低延迟且零输出 token 成本 | 多步推理 |
设置
安装 SDK
Decisions API 需要官方 google-genai SDK 的 3.2 或更高版本(pip install -U google-genai)。
%pip install -U -q google-genai
设置你的 API 密钥
要运行以下单元格,请将你的 API 密钥存储在名为 GEMINI_API_KEY 的 Colab Secret 中。如果你还没有 API 密钥,或者不确定如何创建 Colab Secret,请参阅
Authentication  以获取完整演练。
由于 gemini-decision-1 和 Decisions API 仅在 v1beta 端点上可用——而 google-genai 3.x 默认使用 v1——因此在初始化 genai.Client 时需显式传入 http_options={"api_version": "v1beta"}。
from google import genai
from google.colab import userdata

GEMINI_API_KEY = userdata.get("GEMINI_API_KEY")
client = genai.Client(
    api_key=GEMINI_API_KEY,
    http_options={"api_version": "v1beta"},
)
选择模型
Decisions API 使用 gemini-decision-1 模型:
MODEL_ID = "gemini-decision-1" # @param ["gemini-decision-1"] {"allow-input": true, "isTemplate": true}
1. 快速开始:提出一个是/否问题(noul)
每个 client.decisions.create 请求都需要以下参数:
* model:模型 ID(gemini-decision-1)。
* input:共享上下文(一个 str、Content 字典或 Content 块列表),在所有问题之间统一评估一次。
* questions:一个映射,将调用方定义的问题键([A-Za-z0-9_-]+,最多 64 个字符)映射到问题定义(type、instructions,以及可选/必需的 criteria)。
每个问题都会基于 input 独立评估——问题之间彼此不可见,添加或删除一个问题不会改变其他问题的答案。模型不会看到问题键,因此请在 instructions 中写出完整的问题。
在本示例中,你提出一个 noul 问题——即 Decisions API 的是/否概率类型。它返回:
* noul:校准后的概率 P(yes),介于 0.01 和 0.99 之间(因此 P(no) = 1 - noul)。
* confidence:对获胜方的确定性(max(noul, 1 - noul)),介于 0.50 和 0.99 之间。
安全过滤: 当输入安全过滤器拦截请求时,API 会返回 HTTP400 Bad Request错误而不是answers,并附带错误code(safety、prohibited_content、blocklist、image_safety或content_blocked)和message。
import json

input_text = "The blue mug I ordered on Monday arrived cracked on Wednesday."  # @param {type:"string"}
question_instructions = "Did the item arrive damaged?"  # @param {type:"string"}

result = client.decisions.create(
    model=MODEL_ID,
    input=input_text,
    questions={
        "is_damaged": {
            "type": "noul",
            "instructions": question_instructions,
        },
    },
)

answer = result.answers["is_damaged"]
print(
    f"P(yes) = {answer.noul:.2f} | P(no) = {1 - answer.noul:.2f} | "
    f"confidence = {answer.confidence:.2f}\n"
)
print(json.dumps(result.model_dump(), indent=2))
2. 问题类型(noul、choice 和 score)
| 类型 | 适用场景 | criteria | 答案字段 |
| :--- | :--- | :--- | :--- |
| noul | 是/否检查以及校准后的概率阈值 | 可选:{"true_description": str, "false_description": str} | type、noul、confidence |
| choice | 对固定集合中的选项进行分类、路由或排序 | 必需:选项 ID 到描述的映射(2 到 255 个选项) | type、choice、probabilities、confidence |
| score | 根据有序评分标准对输入进行评分、过滤或排序 | 必需:非空等级描述列表,从最低等级开始(2 到 255 个等级) | type、score、legend、probabilities、confidence |
2.1 noul:是或否
noul(命名源自经过校准的布尔概率,而非生成的 "yes"/"no" token)表示一个二元的是/否决策。
noul 答案包含的内容:
* type:始终为 "noul"。
* noul([0.01, 0.99] 范围内的 float):校准后的概率 P(yes)。由于概率之和为 1.0,因此 P(no) = 1 - answer.noul。
* confidence([0.50, 0.99] 范围内的 float):主导结果(max(noul, 1 - noul))的确定性。
如何解读 noul 值并设定阈值:
* 接近 1.0(例如 noul >= 0.85): 强 是 —— noul 和 confidence 都很高。
* 接近 0.0(例如 noul <= 0.15): 强 否 —— noul 很低,1 - noul 很高,并且 confidence 仍然很高,因为模型确信答案是“否”。
* 接近 0.50(0.40 到 0.60): 临界 / 不确定 —— confidence 接近 0.50,因此应升级给人工处理或运行更深入的检查。
重要:noul始终被限制在0.01和0.99之间。请始终将阈值严格保持在该范围内(诸如noul > 0.99或noul < 0.01的检查永远不会匹配)。
当仅凭问题本身可能有两种解读时,使用可选的 criteria(true_description 和 false_description)来澄清边界情况:
input_text = "Customer returned the sweater because they preferred green over blue."  # @param {type:"string"}
question_instructions = "Is the customer reporting a product defect?"  # @param {type:"string"}

result = client.decisions.create(
    model=MODEL_ID,
    input=input_text,
    questions={
        "is_defect": {
            "type": "noul",
            "instructions": question_instructions,
            "criteria": {
                "true_description": "The product itself is broken or faulty.",
                "false_description": "Preference, sizing, shipping, or pricing complaint.",
            },
        },
    },
)

answer = result.answers["is_defect"]
print(
    f"P(yes) = {answer.noul:.2f} | P(no) = {1 - answer.noul:.2f} | "
    f"confidence = {answer.confidence:.2f}\n"
)
print(json.dumps(answer.model_dump(), indent=2))
2.2 choice:选择一个选项
choice 问题会对一组选项进行评分,并返回获胜选项(choice)以及每个选项的校准概率(probabilities,总和为 1.0),同时返回 confidence。criteria 将每个选项 ID 映射到其适用条件的描述(当选项 ID 本身已足够明确时则为 None)。
按字母顺序排序键与超出范围的输入:
* 在评估之前,API 会按字母顺序(UTF-8字节序)对criteria的键进行排序。在请求中更改键的顺序不会改变选项的位置,而完全相同的概率平局会按字母顺序靠前的键来打破。
*choice始终会在你的选项之间分配概率,即使没有任何选项合适。请对confidence设置阈值以捕获低确定性的输入,或者将问题与单独的noul检查配对,以判断输入是否在范围内(而不是依赖other或none_of_the_above之类的兜底选项)。
input_text = "I was charged twice for my order."  # @param {type:"string"}
question_instructions = "Which department should handle this request?"  # @param {type:"string"}

result = client.decisions.create(
    model=MODEL_ID,
    input=input_text,
    questions={
        "department": {
            "type": "choice",
            "instructions": question_instructions,
            "criteria": {
                "billing": "Charges, invoices, refunds, duplicate charges.",
                "shipping": "Tracking, delivery delays, missing packages.",
                "technical_support": "App crashes, device setup, login issues.",
                "sales": "Product recommendations, enterprise pricing, bulk orders.",
            },
        },
    },
)

answer = result.answers["department"]
print(f"Top choice : {answer.choice} (confidence = {answer.confidence:.2f})\n")
print("Probabilities:")
for dept, prob in answer.probabilities.items():
    print(f"  {dept:<20} {prob:.3f}")
2.3 score:使用文本标准在数值量表上评分
你可能以为 score 类型的问题会接受 [1, 2, 3, 4, 5] 这样的数字。实际上,criteria 接受的是一个有序的文本描述列表(2 到 255 个等级,从低到高排列;对于大多数评分标准,2 到 10 个等级效果最佳):
* 为什么用文本而不是数字: 列表中的位置(0、1、...、N - 1)会自动赋予数值量表。 传入定性的评分标准文本,可以让模型明确 "0" 与 "3" 各自代表什么含义,而不是在一个未定义的数值量表上猜测。
* 数值 score 的计算方式:
probabilities(dict[str, float]):模型为每个索引"0"、"1"、...、str(N - 1)估计一个经过校准的概率 $p_i$,总和为1.0。score([0.00, N - 1.00]范围内的float):概率加权的期望索引 $\sum_i i \cdot p_i$。由于它是在各等级上取平均,score是连续的,可能落在整数之间(例如当等级2承载了大部分概率、同时有一部分概率落在3上时,结果可能是2.08)。legend(dict[str, str]):将每个字符串索引("0"、"1"、...)映射回你的评分标准描述,以便你查询任意等级的含义。confidence([0, 1]范围内的float):分布集中在领先等级上的程度。
提示: 用answer.score / (len(criteria) - 1)可将不同长度评分标准的分数归一化到[0.0, 1.0];当你需要单个离散等级时,可使用max(answer.probabilities, key=answer.probabilities.get)。
input_text = "Export fails in Safari but works in Chrome."  # @param {type:"string"}

criteria = [
    "Trivial: typo or cosmetic defect with no functional impact.",
    "Low: workaround exists; non-blocking.",
    "Medium: core feature impaired for some users.",
    "High: core feature unusable for all users.",
    "Critical: data loss, security vulnerability, or system crash.",
]

result = client.decisions.create(
    model=MODEL_ID,
    input=input_text,
    questions={
        "bug_severity": {
            "type": "score",
            "instructions": "Rate the severity of this software bug.",
            "criteria": criteria,
        },
    },
)

answer = result.answers["bug_severity"]
top_level = max(answer.probabilities, key=answer.probabilities.get)
max_index = len(criteria) - 1
print(
    f"Expected score : {answer.score:.2f} / {max_index:.2f} "
    f"(normalized={answer.score / max_index:.2f})"
)
print(
    f"Top level [{top_level}]  : {answer.legend[top_level]} "
    f"(confidence={answer.confidence:.2f})\n"
)
print("Level probabilities:")
for level_idx in sorted(answer.probabilities, key=int):
    print(f"  [{level_idx}] {answer.probabilities[level_idx]:.3f} - {answer.legend[level_idx]}")
print("\nRaw answer object:")
print(json.dumps(answer.model_dump(), indent=2))
3. 在单个请求中提出多个问题
在单个请求中,针对同一个 input 评估多个带类型的问题。由于 input 在所有问题之间只处理一次,因此每增加一个问题所带来的延迟和 token 开销都可以忽略不计。
3.1 复合客户支持路由
customer_message = "Audio cuts out on the left earcup. Fix it today or I cancel my subscription!"
order_context = {"tier": "platinum", "days_since_purchase": 12}
shared_input = json.dumps({"message": customer_message, "context": order_context}, indent=2)

noul_threshold = 0.50
confidence_threshold = 0.60

result = client.decisions.create(
    model=MODEL_ID,
    input=shared_input,
    questions={
        "is_defect": {
            "type": "noul",
            "instructions": "Is the user reporting physical hardware failure or defect?",
        },
        "next_action": {
            "type": "choice",
            "instructions": "What is the right resolution given `context`?",
            "criteria": {
                "instant_refund": "Refund without return. Low value or clear fault.",
                "replacement_shipment": "Ship a replacement. Customer returns the original.",
                "troubleshooting_flow": "The issue may be fixable by the customer.",
                "human_escalation": None,
            },
        },
        "churn_risk": {
            "type": "score",
            "instructions": "How likely is the customer to churn if the issue is not resolved now?",
            "criteria": [
                "No churn signal",
                "Mild frustration",
                "Mentions alternatives",
                "Threatens to cancel",
            ],
        },
    },
)

a = result.answers
if a["is_defect"].noul > noul_threshold and a["next_action"].confidence > confidence_threshold:
    action = a["next_action"].choice
else:
    action = "human_escalation"

next_act = a["next_action"]
print(f"is_defect P(yes) : {a['is_defect'].noul:.2f}")
print(f"next_action      : {next_act.choice} (confidence={next_act.confidence:.2f})")
print(f"churn_risk score : {a['churn_risk'].score:.2f} / 3.00")
print(f"--> Routed action: {action}")
3.2 单次前向传播中对候选与选项进行排序
由于 score 返回连续期望值,而 choice 返回各选项的校准概率,你可以在一次预填充(prefill)中完成检索文档的排序或顶级工具的选择:
- 上下文内候选排序(
score): 将查询和候选段落传入input,为每个候选提出一个score问题,并按.score降序排序。 - Top-K 选项排序(
choice): 按.probabilities降序排序,以路由到顶级工具或类别。
# 1. In-context candidate ranking: score 4 retrieved passages in a single pass
query = "How do I authenticate to the Gemini API using an environment variable?"
candidates = {
    "doc_1": (
        "Rate limits depend on your usage tier (Free, Tier 1, Tier 2) and are measured in RPM/TPM."
    ),
    "doc_2": (
        "Set the GEMINI_API_KEY environment variable in your shell, then initialize genai.Client() "
        "with no arguments; the SDK reads GEMINI_API_KEY automatically."
    ),
    "doc_3": (
        "You can pass an API key explicitly to genai.Client(api_key='YOUR_KEY') when "
        "initializing the client in Python."
    ),
    "doc_4": (
        "Use the Files API (client.files.upload) to upload large audio or video files before "
        "referencing them in requests."
    ),
}
relevance_rubric = [
    "Irrelevant: does not address the user's question.",
    "Tangential: mentions related concepts, but does not answer the question.",
    "Partial: answers a closely related question, but misses the specific requirement.",
    "Exact match: directly and completely answers the user's question.",
]

rank_result = client.decisions.create(
    model=MODEL_ID,
    input=json.dumps({"query": query, "candidates": candidates}, indent=2),
    questions={
        doc_id: {
            "type": "score",
            "instructions": f"How well does candidate `{doc_id}` answer `query`?",
            "criteria": relevance_rubric,
        }
        for doc_id in candidates
    },
)

print("Ranked candidates (by continuous score):")
for rank, (doc_id, ans) in enumerate(
    sorted(rank_result.answers.items(), key=lambda kv: kv[1].score, reverse=True), 1
):
    score_desc = f"score={ans.score:.2f}/3.00 (confidence={ans.confidence:.2f})"
    print(f"  #{rank} {doc_id}: {score_desc} -> {candidates[doc_id][:50]}...")

# 2. Top-K option ranking: sort `choice` probabilities to select top tools
user_task = (
    "Can you compare our Q3 cloud spend CSV against the Q2 invoice PDF and plot the variance?"
)
route_result = client.decisions.create(
    model=MODEL_ID,
    input=user_task,
    questions={
        "tool_route": {
            "type": "choice",
            "instructions": "Which specialist tool is most relevant to fulfill this user request?",
            "criteria": {
                "code_interpreter": (
                    "Run Python/pandas data analysis and generate charts from tabular data."
                ),
                "document_reader": "Extract tables and text from uploaded PDF documents.",
                "web_search": "Search the public web for live news or documentation.",
                "account_billing": (
                    "Modify subscription plans, payment methods, or billing addresses."
                ),
            },
        }
    },
)

print("\nTop-K tool routing (by calibrated probability):")
for rank, (tool_id, prob) in enumerate(
    sorted(
        route_result.answers["tool_route"].probabilities.items(),
        key=lambda kv: kv[1],
        reverse=True,
    ),
    1,
):
    print(f"  #{rank} {tool_id:<18} P={prob:.3f}")
4. 多模态输入与媒体解析
input 接受 text、image、audio、video 和 document(application/pdf)内容块,使用与 Interactions API 相同的块结构:
* 在 data 中传入 base64 编码的字节(每次请求最大 100 MB,PDF 最大 50 MB)、Files API URI(file.uri),或在 uri 中传入公共 HTTPS / 签名 URL(每个外部 URL 最大 15 MB)。
* decisions.create 不支持直接使用 Cloud Storage(gs://)URI 和 YouTube URL。
* 始终将 mime_type 设置为真实格式(application/octet-stream 会被拒绝)。
* 在 image 和 video 块上设置 resolution("low"、"medium"、"high",仅图像支持 "ultra_high"),以控制每个条目的 token 用量:
| 媒体 | 默认 | resolution: "low" |
| :--- | :--- | :--- |
| 图像 | ~1,090 tokens | ~260 tokens(low、medium、high、ultra_high) |
| PDF 页面(document) | ~520 tokens + 提取的文本 | 不支持 |
| 视频 | 1 fps(~66 图像 tokens + ~25 音频 tokens/秒) | ~66 图像 tokens/秒(low、medium、high) |
| 音频 | ~25 tokens/秒 | 不支持 |
4.1 图像(base64 data 与 resolution)
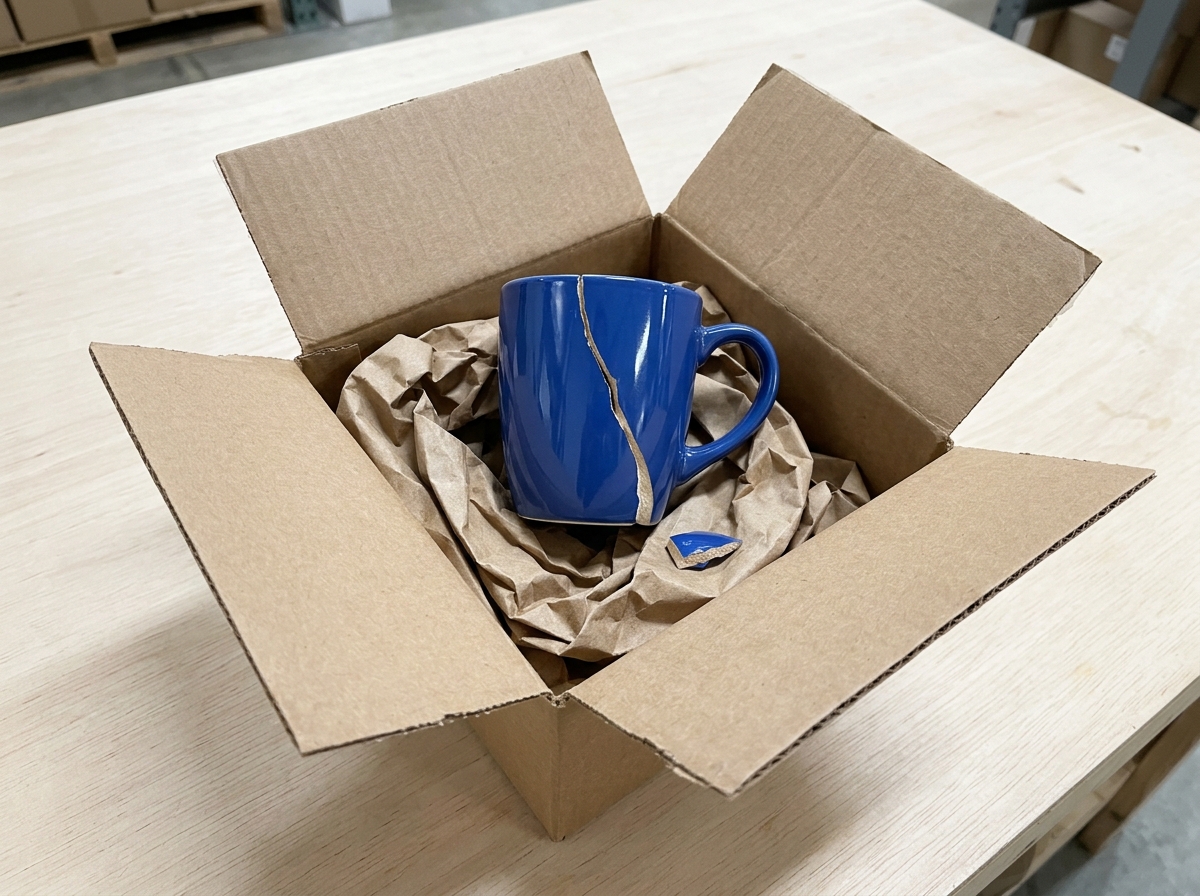
从 Cookbook 媒体存储桶加载一张产品退货照片,将其内联显示,并使用 base64 data 和 resolution="low" 对照片评估三个同时提出的问题(noul、choice 和 score):
import base64
from IPython.display import Image, display
import requests

image_url = "https://storage.googleapis.com/generativeai-downloads/images/damaged_blue_mug.jpg"
response = requests.get(image_url, timeout=30)
response.raise_for_status()
image_bytes = response.content
image_b64 = base64.b64encode(image_bytes).decode("utf-8")
image_resolution = "low"  # @param ["low", "medium", "high", "ultra_high"]

display(Image(data=image_bytes, width=480))

result = client.decisions.create(
    model=MODEL_ID,
    input=[
        {"type": "text", "text": "Inspect this customer return photo."},
        {
            "type": "image",
            "data": image_b64,
            "mime_type": "image/jpeg",
            "resolution": image_resolution,
        },
    ],
    questions={
        "is_damaged": {
            "type": "noul",
            "instructions": "Does the photo show physical damage to the product?",
        },
        "disposition": {
            "type": "choice",
            "instructions": "What warehouse disposition applies to this return?",
            "criteria": {
                "restock_new": "Item is unopened and in pristine condition.",
                "refurbish": "Minor cosmetic wear that can be cleaned or repackaged.",
                "scrap_and_refund": "Item is cracked, broken, or chipped beyond repair.",
            },
        },
        "damage_severity": {
            "type": "score",
            "instructions": "How severe is the damage visible on the item?",
            "criteria": [
                "None: intact with no visible damage.",
                "Minor: light surface scuff only, usable.",
                "Severe: structural crack, chip, or broken parts.",
            ],
        },
    },
)

disp = result.answers["disposition"]
print(f"is_damaged P(yes) : {result.answers['is_damaged'].noul:.2f}")
print(f"disposition       : {disp.choice} (confidence={disp.confidence:.2f})")
print(f"damage_severity   : {result.answers['damage_severity'].score:.2f} / 2.00")
print("\nToken usage by modality:")
print(json.dumps(result.usage.model_dump(), indent=2))
4.2 音频、视频和 PDF(通过公共 HTTPS uri)
你可以通过 Files API URI 或公共 HTTPS / 签名 uri 传递任何受支持的媒体块——包括 PDF 文档(type="document" 且 mime_type="application/pdf")——每个外部 URL 最大 15 MB。评估一个 MP3 音频片段、一个 resolution="low" 的 MP4 视频片段,以及一份 PDF 用户指南:
# 1. Audio evaluation via public HTTPS URI
audio_uri = "https://storage.googleapis.com/generativeai-downloads/data/Apollo-11_Day-01-Highlights-10s.mp3"
audio_question = "Is the speaker talking about spaceflight or a rocket launch?"

audio_result = client.decisions.create(
    model=MODEL_ID,
    input=[
        {
            "type": "audio",
            "uri": audio_uri,
            "mime_type": "audio/mp3",
        },
    ],
    questions={
        "mentions_launch": {
            "type": "noul",
            "instructions": audio_question,
        },
    },
)
ans_audio = audio_result.answers["mentions_launch"]
print(
    f"Audio mentions_launch P(yes): {ans_audio.noul:.2f} "
    f"(confidence={ans_audio.confidence:.2f})"
)

# 2. Video evaluation via public HTTPS URI at low resolution
video_uri = "https://storage.googleapis.com/generativeai-downloads/videos/ForBiggerBlazes.mp4"
video_question = "Does the video show fire or flames?"
video_resolution = "low"  # @param ["low", "medium", "high"]

video_result = client.decisions.create(
    model=MODEL_ID,
    input=[
        {
            "type": "video",
            "uri": video_uri,
            "mime_type": "video/mp4",
            "resolution": video_resolution,
        },
    ],
    questions={
        "shows_fire": {
            "type": "noul",
            "instructions": video_question,
        },
    },
)
ans_video = video_result.answers["shows_fire"]
print(
    f"Video shows_fire P(yes)     : {ans_video.noul:.2f} "
    f"(confidence={ans_video.confidence:.2f})"
)

# 3. PDF evaluation via public HTTPS URI (type="document", up to 15 MB)
pdf_uri = "https://storage.googleapis.com/generativeai-downloads/data/Nest-Cam-IQ-Outdoor_UserGuide-en-us.pdf"
pdf_question = "Does this document cover installation instructions for an outdoor camera?"

pdf_result = client.decisions.create(
    model=MODEL_ID,
    input=[
        {
            "type": "document",
            "uri": pdf_uri,
            "mime_type": "application/pdf",
        },
    ],
    questions={
        "is_camera_guide": {
            "type": "noul",
            "instructions": pdf_question,
        },
    },
)
ans_pdf = pdf_result.answers["is_camera_guide"]
print(
    f"PDF is_camera_guide P(yes)  : {ans_pdf.noul:.2f} "
    f"(confidence={ans_pdf.confidence:.2f})\n"
)
print("PDF token usage (pages are reported under 'image', extracted text under 'text'):")
print(json.dumps(pdf_result.usage.model_dump(), indent=2))
5. 最佳实践与请求限制
编写优质问题
* 让每个问题聚焦于单一决策或评分标准:当标准明确时,复杂评分标准可以在一个问题中完成;你也可以将独立的检查项拆分为同一请求中的多个问题,并在代码中合并答案。
* 在 instructions 中写出完整问题:模型永远看不到问题键("is_damaged"、"department")或你的变量名。
* 为每个 choice 选项和 score 等级提供简短描述:让相邻的 score 等级明显不同,并保持 score 刻度线性(因为 score 会对数组索引 0, 1, 2, ... 求平均,像 1, 10, 100, 1000 这样的指数刻度会扭曲期望值)。
* 为不匹配任何 choice 选项的输入做好规划:在依据首选选项行动之前检查 confidence,或将 choice 与 noul 范围检查配对使用(例如*“这条消息是关于订单的吗?”*)。
* 优先使用肯定式表述:询问*“等级是 Gold 吗?”*并在代码中计算 1 - noul,而不是询问*“等级不是 Gold 吗?”*这样的否定式问题。
* 只发送问题所需的字段,并在代码中比较数字/日期:无关内容会降低准确率。在代码中比较数字、日期和时长,然后将结果或命名分桶传入 input。
* 将 input 视为不可信内容:input 中的文本可能会为自身的分类进行争辩。编写明确的标准,用对抗性示例进行测试,并对高风险操作(如付款)保留人工或第二重检查。
请求限制
| 限制项 | 值 |
| :--- | :--- |
| 每次请求的问题数 | 1 到 1,000(受 262,144 token 上下文窗口限制) |
| 每个 choice 问题的选项数 | 2 到 255 |
| 每个 score 问题的等级数 | 2 到 255 个非空字符串(大多数评分标准建议 2 到 10) |
| 问题键 | 1 到 64 个 ASCII 字符,匹配 [A-Za-z0-9_-]+ |
| 选项键 | 1 到 128 个字符(最多 512 个 UTF-8 字节;允许内部 ASCII 空格,不允许前导/尾随空格或控制字符) |
| 上下文窗口 | input 和所有问题合计 262,144 个 token |
| JSON 嵌套深度 | 100 层 |
| 输出 token 成本 | 0(total_output_tokens 始终为 0) |
| 默认速率限制 | 适用标准 Gemini API 层级配额(参见速率限制) |
当前限制
* API 版本:仅在 Gemini Developer API(v1beta)上提供,且仅支持 gemini-decision-1。在 google-genai 3.2+ 中需显式传入 http_options={"api_version": "v1beta"}。
* 仅文本的问题指令:问题必须是文本;多模态内容应放在 input 中。
* 媒体来源:将图像、音频、视频或 PDF(type="document")以 base64 编码的 data(PDF 最大 50 MB,单次请求最大 100 MB)、Files API URI(file.uri)或公开/签名的 HTTPS uri(每个外部 URL 最大 15 MB)传入。不支持直接使用 gs:// URI 和 YouTube URL。
* 不支持上下文缓存、Batch API 或 Flex/Priority 层级:跨请求重复相同的 input 时,每次都会完整计入。
后续步骤
* 在 Gemini API 文档 和 Google AI Studio 文档 中进一步了解 Decisions API。
* 探索相关快速入门:
* Interactions API:用于生成内容、工具调用和多轮对话。
* JSON 模式:用于按照自定义 Pydantic schema 提取结构化对象。
* 提示工程:用于学习高级提示工程技巧。
常见问题
常见错误:未指定 v1beta 导致 404 或模型不可用;noul 阈值写成 >0.99 或 <0.01 永不命中;把 choice 当作可拒识分类器而忽略 confidence;score 使用指数刻度扭曲期望值;问题键含非法字符或超 64 字符;mime_type 缺失或为 application/octet-stream 被拒;使用 gs:// 或 YouTube URL;外部 URL 超 15 MB、PDF 超 50 MB、单请求超 100 MB;安全过滤返回 400 及 safety/prohibited_content 等 code。排查时先打印 result.model_dump() 与 usage,核对 token 分布与概率和是否为 1.0,用对抗性输入测试阈值稳定性,对低置信度样本升级人工。
企业应用扩展
生产优化建议:为每类问题建立离线标注集校准阈值与 confidence 下限;对 choice 增加前置 noul 范围检查替代兜底选项;用 score/(N-1) 归一化跨评分标准比较;批量场景下把候选段落放入同一 input 用多 score 问题排序,减少往返;对高风险动作保留二次校验或人工复核;监控概率分布漂移与安全过滤命中率;注意无上下文缓存,重复 input 每次全量计费,应合并请求并控制媒体分辨率以降低 token。
总结
本文面向有编程基础的开发者,系统讲解 Gemini Decisions API 的工程用法。文章说明为何在路由、分类、评分等决策场景中应使用 gemini-decision-1 而非生成式接口,剖析 noul、choice、score 三种问题类型的概率语义与数据流,给出 SDK 安装、v1beta 端点配置、多模态输入与单请求多问题的完整实践步骤,并总结阈值设定、置信度过滤、常见错误排查与生产优化建议。
- --
内容来源与验证
- 内容等级:PREMIUM_A
- 质量等级:A
- 难度:中级
- 验证等级:V1
- 原文作者:
- 原文日期:
- 来源许可:Apache-2.0
- 来源版本:
d6618e3ef4206a25164edaa5b7cc9f716048cba3 - 查看原文
站内还有更多完整实战教程
加入会员,解锁全部教程、完整代码与持续更新内容。
加入会员