使用Agents SDK构建深度研究API:实战指南
技术背景
深度研究API与Agents SDK的出现,解决了传统问答系统在处理需要多步推理、信息综合和工具调用的复杂研究任务时的不足。普通API适合简单查询,但面对需要规划、综合和外部知识获取的任务时,智能体工作流能显著提升输出质量。本教程适用于需要构建自动化研究工具的场景,如竞争情报、学术综述、市场分析等。主要限制包括API成本较高、依赖外部搜索质量,以及需要合理设计智能体交互以避免冗余或错误。
核心原理
核心原理是基于智能体(Agent)的编排,每个智能体负责特定子任务,通过交接(handoff)机制协作。分诊智能体判断是否需要澄清,澄清智能体收集缺失信息,指令构建智能体将用户查询转化为详细研究简报,研究智能体执行网络搜索和MCP文件检索,并流式返回进度。关键设计决策包括:使用gpt-5.6-terra平衡智能与成本,gpt-4o-mini用于轻量级任务;通过结构化输出(Pydantic模型)确保澄清问题格式;利用流式事件实现透明度和实时反馈。
架构分析
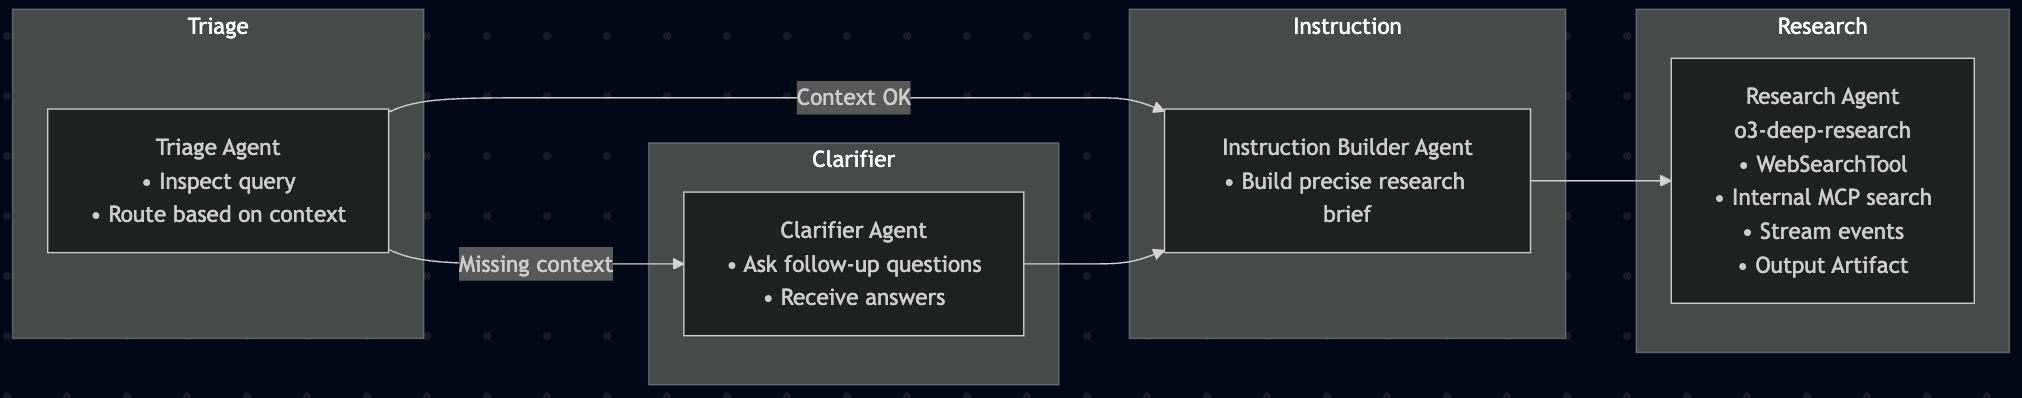
系统采用模块化多智能体架构,包含四个核心组件:分诊智能体(Triage Agent)负责路由决策,澄清智能体(Clarifying Agent)生成结构化问题,指令构建智能体(Instruction Agent)重写查询为详细指令,研究智能体(Research Agent)集成WebSearchTool和HostedMCPTool执行研究。数据流为:用户查询→分诊→(澄清→)指令→研究→输出。关键设计决策包括:使用handoffs实现智能体间无缝切换,通过RunConfig控制追踪,利用流式事件驱动交互。生产环境可扩展为更多专用智能体,并支持自定义工具集成。
完整实战教程
深度研究智能体食谱
本食谱演示如何使用OpenAI深度研究API和OpenAI Agents SDK构建智能体研究流程。它是基础食谱的延续,如果你尚未熟悉该内容,建议先阅读。
你将学习如何编排单智能体和多智能体管道、丰富用户查询以最大化输出质量、流式传输研究进度、集成网络搜索和用于内部文件搜索的MCP,以及构建稳健的研究应用。
对于需要规划、综合、工具使用或多步推理的任务,请考虑使用深度研究智能体。对于琐碎的事实查找、简单问答或短对话,请勿使用深度研究,普通的openai.responsesAPI会更快且更便宜。
先决条件
* OpenAI API 密钥(在环境中设置为 OPENAI_API_KEY)
* Agents SDK 和 OpenAI Python SDK
设置
*安装依赖*
%pip install --upgrade "openai>=1.88" "openai-agents>=0.0.19"
导入库并配置客户端
零数据保留
我们通过下面的 os.environ 设置禁用数据保留。这允许企业在零数据保留环境中使用深度研究。如果数据保留对您来说不是一项硬性约束,那么建议保持启用状态,以便您可以为代理工作流获得自动化的可追溯性,并与其他平台工具(如评估和微调)进行深度集成。
import os
from agents import Agent, Runner, WebSearchTool, RunConfig, set_default_openai_client, HostedMCPTool
from typing import List, Dict, Optional
from pydantic import BaseModel
from openai import AsyncOpenAI

# Use env var for API key and set a long timeout
client = AsyncOpenAI(timeout=600.0)
set_default_openai_client(client)
os.environ["OPENAI_AGENTS_DISABLE_TRACING"] = "1" # Disable tracing for Zero Data Retention (ZDR) Organizations
基础深度研究代理
基础研究代理使用 gpt-5.6-terra 模型进行深度研究,该模型在智能和成本之间取得了平衡。它使用 WebSearchTool 访问公共互联网,并将其发现直接流式传输回笔记本。
学习目标:
完成本节后,您将能够运行单代理研究任务并流式传输其进度。
# Define the research agent
research_agent = Agent(
    name="Research Agent",
    model="gpt-5.6-terra",
    tools=[WebSearchTool()],
    instructions="You perform deep empirical research based on the user's question."
)

# Async function to run the research and print streaming progress
async def basic_research(query):
    print(f"Researching: {query}")
    result_stream = Runner.run_streamed(
        research_agent,
        query
    )

    async for ev in result_stream.stream_events():
        if ev.type == "agent_updated_stream_event":
            print(f"\n--- switched to agent: {ev.new_agent.name} ---")
            print(f"\n--- RESEARCHING ---")
        elif (
            ev.type == "raw_response_event"
            and hasattr(ev.data, "item")
            and hasattr(ev.data.item, "action")
        ):
            action = ev.data.item.action or {}
            if action.get("type") == "search":
                print(f"[Web search] query={action.get('query')!r}")

    # streaming is complete → final_output is now populated
    return result_stream.final_output

# Run the research and print the result
result = await basic_research("Research the economic impact of semaglutide on global healthcare systems.")
print(result)
带澄清的多智能体研究
多智能体深度研究
思考一下如何进一步提升“深度研究”所产生的研究质量。在这种情况下,我们利用多智能体架构,在将用户查询提交给深度研究智能体之前,用关于用户查询以及我们期望在最终研究报告中看到的内容的_更多信息_来丰富提示词。
子代理提示词增强
支持性代理提示词经过专门设计,通过为用户初始查询提供结构和严谨性,来提高最终研究输出的质量。
# ─────────────────────────────────────────────────────────────
#  Prompts
# ─────────────────────────────────────────────────────────────

CLARIFYING_AGENT_PROMPT =  """
    If the user hasn't specifically asked for research (unlikely), ask them what research they would like you to do.

        GUIDELINES:
        1. **Be concise while gathering all necessary information** Ask 2–3 clarifying questions to gather more context for research.
        - Make sure to gather all the information needed to carry out the research task in a concise, well-structured manner. Use bullet points or numbered lists if appropriate for clarity. Don't ask for unnecessary information, or information that the user has already provided.
        2. **Maintain a Friendly and Non-Condescending Tone**
        - For example, instead of saying “I need a bit more detail on Y,” say, “Could you share more detail on Y?”
        3. **Adhere to Safety Guidelines**
        """

RESEARCH_INSTRUCTION_AGENT_PROMPT = """

        Based on the following guidelines, take the users query, and rewrite it into detailed research instructions. OUTPUT ONLY THE RESEARCH INSTRUCTIONS, NOTHING ELSE. Transfer to the research agent.

        GUIDELINES:
        1. **Maximize Specificity and Detail**
        - Include all known user preferences and explicitly list key attributes or dimensions to consider.
        - It is of utmost importance that all details from the user are included in the expanded prompt.

        2. **Fill in Unstated But Necessary Dimensions as Open-Ended**
        - If certain attributes are essential for a meaningful output but the user has not provided them, explicitly state that they are open-ended or default to “no specific constraint.”

        3. **Avoid Unwarranted Assumptions**
        - If the user has not provided a particular detail, do not invent one.
        - Instead, state the lack of specification and guide the deep research model to treat it as flexible or accept all possible options.

        4. **Use the First Person**
        - Phrase the request from the perspective of the user.

        5. **Tables**
        - If you determine that including a table will help illustrate, organize, or enhance the information in your deep research output, you must explicitly request that the deep research model provide them.
        Examples:
        - Product Comparison (Consumer): When comparing different smartphone models, request a table listing each model’s features, price, and consumer ratings side-by-side.
        - Project Tracking (Work): When outlining project deliverables, create a table showing tasks, deadlines, responsible team members, and status updates.
        - Budget Planning (Consumer): When creating a personal or household budget, request a table detailing income sources, monthly expenses, and savings goals.
        Competitor Analysis (Work): When evaluating competitor products, request a table with key metrics—such as market share, pricing, and main differentiators.

        6. **Headers and Formatting**
        - You should include the expected output format in the prompt.
        - If the user is asking for content that would be best returned in a structured format (e.g. a report, plan, etc.), ask the Deep Research model to “Format as a report with the appropriate headers and formatting that ensures clarity and structure.”

        7. **Language**
        - If the user input is in a language other than English, tell the model to respond in this language, unless the user query explicitly asks for the response in a different language.

        8. **Sources**
        - If specific sources should be prioritized, specify them in the prompt.
        - Prioritize Internal Knowledge. Only retrieve a single file once.
        - For product and travel research, prefer linking directly to official or primary websites (e.g., official brand sites, manufacturer pages, or reputable e-commerce platforms like Amazon for user reviews) rather than aggregator sites or SEO-heavy blogs.
        - For academic or scientific queries, prefer linking directly to the original paper or official journal publication rather than survey papers or secondary summaries.
        - If the query is in a specific language, prioritize sources published in that language.

        IMPORTANT: Ensure that the complete payload to this function is valid JSON
        IMPORTANT: SPECIFY REQUIRED OUTPUT LANGUAGE IN THE PROMPT
        """
四智能体深度研究流水线
- 分流智能体
- 检查用户的查询
- 如果缺少上下文,则路由到澄清智能体;否则路由到指令智能体
- 澄清智能体
- 提出后续问题
- 等待用户(或模拟)回答
- 指令构建智能体
- 将增强后的输入转换为精确的研究简报
- 研究智能体 (
gpt-5.6-sol)
- 使用
WebSearchTool进行网络规模的实证研究 - 使用 MCP 对内部知识库进行搜索,如果有相关文档,智能体将相关片段纳入其参考资料中。
- 流式传输中间事件以提高透明度
- 输出最终研究工件(我们稍后解析)
 要更深入地了解 MCP 服务器是如何构建的,请参阅此资源。
# ─────────────────────────────────────────────────────────────
# Structured outputs (needed only for Clarifying agent)
# ─────────────────────────────────────────────────────────────
class Clarifications(BaseModel):
    questions: List[str]

# ─────────────────────────────────────────────────────────────
# Agents
# ─────────────────────────────────────────────────────────────
research_agent = Agent(
    name="Research Agent",
    model="gpt-5.6-sol",
    instructions="Perform deep empirical research based on the user's instructions.",
    tools=[WebSearchTool(),
           HostedMCPTool(
            tool_config={
                "type": "mcp",
                "server_label": "file_search",
                "server_url": "https://<url>/sse",
                "require_approval": "never",
            }
        )
    ]
)

instruction_agent = Agent(
    name="Research Instruction Agent",
    model="gpt-4o-mini",
    instructions=RESEARCH_INSTRUCTION_AGENT_PROMPT,
    handoffs=[research_agent],
)

clarifying_agent = Agent(
    name="Clarifying Questions Agent",
    model="gpt-4o-mini",
    instructions=CLARIFYING_AGENT_PROMPT,
    output_type=Clarifications,
    handoffs=[instruction_agent],
)

triage_agent = Agent(
    name="Triage Agent",
    instructions=(
        "Decide whether clarifications are required.\n"
        "• If yes → call transfer_to_clarifying_questions_agent\n"
        "• If no  → call transfer_to_research_instruction_agent\n"
        "Return exactly ONE function-call."
    ),
    handoffs=[clarifying_agent, instruction_agent],
)


# ─────────────────────────────────────────────────────────────
#  Auto-clarify helper
# ─────────────────────────────────────────────────────────────
async def basic_research(
    query: str,
    mock_answers: Optional[Dict[str, str]] = None,
    verbose: bool = False,
):
    stream = Runner.run_streamed(
        triage_agent,
        query,
        run_config=RunConfig(tracing_disabled=True),
    )

    async for ev in stream.stream_events():
        if isinstance(getattr(ev, "item", None), Clarifications):
            reply = []
            for q in ev.item.questions:
                ans = (mock_answers or {}).get(q, "No preference.")
                reply.append(f"**{q}**\n{ans}")
            stream.send_user_message("\n\n".join(reply))
            continue
        if verbose:
            print(ev)

    #return stream.final_output
    return stream

# ─────────────────────────────────────────────────────────────
#  Example run
# ─────────────────────────────────────────────────────────────
result = await basic_research(
    "Research the economic impact of semaglutide on global healthcare systems.",
    mock_answers={},   # or provide canned answers
)
Agent 交互流程
虽然 Agent SDK 原生提供了追踪功能,但你可能希望打印出人类可读的高层 Agent 交互流程,包括工具调用。运行 print_agent_interaction 可以获取简化的可读 Agent 步骤序列,包括:Agent 名称、事件类型(交接、工具调用、消息输出)、简要的工具调用信息(工具名称和参数)。
import json

def parse_agent_interaction_flow(stream):
    print("=== Agent Interaction Flow ===")
    count = 1

    for item in stream.new_items:
        # Agent name, fallback if missing
        agent_name = getattr(item.agent, "name", "Unknown Agent") if hasattr(item, "agent") else "Unknown Agent"

        if item.type == "handoff_call_item":
            func_name = getattr(item.raw_item, "name", "Unknown Function")
            print(f"{count}. [{agent_name}] → Handoff Call: {func_name}")
            count += 1

        elif item.type == "handoff_output_item":
            print(f"{count}. [{agent_name}] → Handoff Output")
            count += 1

        elif item.type == "mcp_list_tools_item":
            print(f"{count}. [{agent_name}] → mcp_list_tools_item")
            count += 1

        elif item.type == "reasoning_item":
            print(f"{count}. [{agent_name}] → Reasoning step")
            count += 1

        elif item.type == "tool_call_item":
            tool_name = getattr(item.raw_item, "name", None)

            # Skip tool call if tool_name is missing or empty
            if not isinstance(tool_name, str) or not tool_name.strip():
                continue  # skip silently

            tool_name = tool_name.strip()

            args = getattr(item.raw_item, "arguments", None)
            args_str = ""

            if args:
                try:
                    parsed_args = json.loads(args)
                    if parsed_args:
                        args_str = json.dumps(parsed_args)
                except Exception:
                    if args.strip() and args.strip() != "{}":
                        args_str = args.strip()

            args_display = f" with args {args_str}" if args_str else ""

            print(f"{count}. [{agent_name}] → Tool Call: {tool_name}{args_display}")
            count += 1

        elif item.type == "message_output_item":
            print(f"{count}. [{agent_name}] → Message Output")
            count += 1

        else:
            print(f"{count}. [{agent_name}] → {item.type}")
            count += 1

# Example usage:
parse_agent_interaction_flow(result)
引用
以下是一个 Python 代码片段,用于提取并打印与最终输出相关的 URL 引用:
def print_final_output_citations(stream, preceding_chars=50):
    # Iterate over new_items in reverse to find the last message_output_item(s)
    for item in reversed(stream.new_items):
        if item.type == "message_output_item":
            for content in getattr(item.raw_item, 'content', []):
                if not hasattr(content, 'annotations') or not hasattr(content, 'text'):
                    continue
                text = content.text
                for ann in content.annotations:
                    if getattr(ann, 'type', None) == 'url_citation':
                        title = getattr(ann, 'title', '<no title>')
                        url = getattr(ann, 'url', '<no url>')
                        start = getattr(ann, 'start_index', None)
                        end = getattr(ann, 'end_index', None)

                        if start is not None and end is not None and isinstance(text, str):
                            # Calculate preceding snippet start index safely
                            pre_start = max(0, start - preceding_chars)
                            preceding_text = text[pre_start:start].replace('\n', ' ').strip()
                            excerpt = text[start:end].replace('\n', ' ').strip()
                            print("# --------")
                            print("# MCP CITATION SAMPLE:")
                            print(f"#   Title:       {title}")
                            print(f"#   URL:         {url}")
                            print(f"#   Location:    chars {start}–{end}")
                            print(f"#   Preceding:   '{preceding_text}'")
                            print(f"#   Excerpt:     '{excerpt}'\n")
                        else:
                            # fallback if no indices available
                            print(f"- {title}: {url}")
            break

# Usage
print_final_output_citations(result)
## Deep Research Research Report

print(result.final_output)
结论
通过本笔记本中的模式,您现在拥有了使用 OpenAI Deep Research Agents 构建可扩展、生产级研究流程的基础。这些示例不仅展示了如何编排多代理管道和流式传输研究进度,还展示了如何集成网络搜索和 MCP 以获取外部知识。
通过利用代理工作流,您可以超越简单的问答,处理需要规划、综合和工具使用的复杂多步骤研究任务。模块化的多代理设计:分诊、澄清、指令和研究代理,使您能够将这些管道适应广泛的领域和用例,从医疗保健和金融到技术尽职调查和市场分析。
随着 Deep Research API 和 Agents SDK 的不断发展,这些模式将帮助您保持在自动化、数据驱动研究的前沿。无论您是在构建内部知识工具、自动化竞争情报,还是为专家分析师提供支持,这些工作流都提供了一个强大且可扩展的起点。
祝您研究愉快!
常见问题
常见错误包括:1) API密钥未设置或超时,导致请求失败,应确保环境变量正确并设置较长超时(如600秒)。2) 流式事件处理不当,忽略raw_response_event中的搜索动作,导致进度显示不完整,需正确解析事件类型。3) MCP服务器连接失败,检查URL和SSE端点,确保网络可达。4) 澄清循环无限,需设置mock_answers或超时机制。5) 输出解析错误,因final_output可能为None,需在流结束后访问。排查方法:启用追踪(除非ZDR要求),打印事件流,检查工具调用参数。生产优化:使用缓存减少重复搜索,设置并发限制,监控API成本,采用异步处理提升吞吐量。
企业应用扩展
可扩展方向包括:1) 集成更多MCP服务器,如数据库查询或内部API,丰富知识源。2) 增加评估模块,自动评估研究质量并反馈优化。3) 实现用户反馈循环,动态调整澄清问题。4) 部署为REST API,结合前端实现交互式研究工具。5) 利用Agents SDK的追踪功能进行性能监控和调试。6) 针对特定领域(如医疗、金融)定制指令模板,提升输出相关性。
总结
本教程面向有编程基础的开发者,深入讲解如何利用OpenAI Agents SDK构建生产级深度研究智能体。内容涵盖单智能体与多智能体管道编排、用户查询增强、流式进度传输、网络搜索与MCP集成,以及稳健应用构建。通过分诊、澄清、指令构建和研究四个智能体的协作,实现复杂研究任务的高效处理。教程提供完整代码示例、架构解析、常见错误排查及生产优化建议,帮助开发者掌握AI工程实践中的关键设计模式。
- --
内容来源与验证
- 内容等级:PREMIUM_A
- 质量等级:A
- 难度:高级
- 验证等级:V1
- 原文作者:alwell-kevin, glojain
- 原文日期:2025-06-25
- 来源许可:MIT
- 来源版本:
7b1d9fac26e09b504018c8a02eba822bd4e3390f - 查看原文
站内还有更多完整实战教程
加入会员,解锁全部教程、完整代码与持续更新内容。
加入会员