构建智能体改进循环:利用追踪、评估与Codex
技术背景
在AI工程实践中,智能体系统常面临行为不可控、评估困难、迭代缓慢等问题。传统的提示调优缺乏系统性,难以持续改进。本教程提出的改进循环,通过追踪、反馈、评估和优化,将智能体的行为改进转化为可重复、可验证的工程流程。该技术适用于需要持续优化智能体行为的场景,如客服、金融分析、代码生成等。主要限制包括依赖高质量反馈、评估设计需人工审查,以及自动化程度需谨慎控制。
核心原理
核心原理是构建一个闭环系统,其中追踪记录智能体行为,反馈(人工和模型)提供改进信号,评估将反馈转化为可复用的测试,HALO分析证据并生成优化建议,Codex实施变更。数据流为:智能体运行产生追踪,追踪被审查并添加反馈,反馈用于生成评估,评估验证当前框架,HALO结合所有证据生成交接文档,Codex据此修改框架,然后循环重复。关键设计决策包括:将框架定义为完整契约(指令、工具、路由等),使用合成数据确保可复现性,以及将人工反馈作为一等公民。
架构分析
系统架构分为多个模块:数据生成模块创建合成尽职调查材料;智能体模块基于OpenAI Agents SDK构建,包含系统提示、工具策略和输出契约;追踪模块通过自定义导出器将SDK spans转换为HALO可读的JSONL;反馈模块模拟人工和LLM反馈;评估模块使用Promptfoo生成并运行测试;优化模块使用HALO分析并生成交接文档;实施模块由Codex执行。设计思想强调模块化、可扩展性和人工审查门禁,支持从半自动到全自动的演进。
完整实战教程
构建智能体改进循环:利用追踪、评估与Codex
本笔记本为智能体构建了一个改进飞轮。我们从真实追踪开始,添加人工和模型反馈,将反馈转化为评估,并利用所得证据为Codex提出下一步的框架变更建议。
你将:
- 创建一个基于OpenAI Agents SDK的金融分析师
- 在合成公司数据上运行它并捕获追踪
- 从这些运行中添加示例人工反馈和LLM生成的反馈
- 将反馈转化为Promptfoo评估,以便后续重新运行
- 使用HALO对下一步框架变更进行排序,并编写一份Codex可执行的交接文档
在本笔记本中,框架是围绕模型的完整契约,包括指令、工具、路由、输出要求和验证检查。
该飞轮保留了每次运行中学到的经验。追踪显示发生了什么,反馈解释了什么重要,评估使这些期望可复用,而Codex可以基于生成的变更集采取行动。
你将构建什么
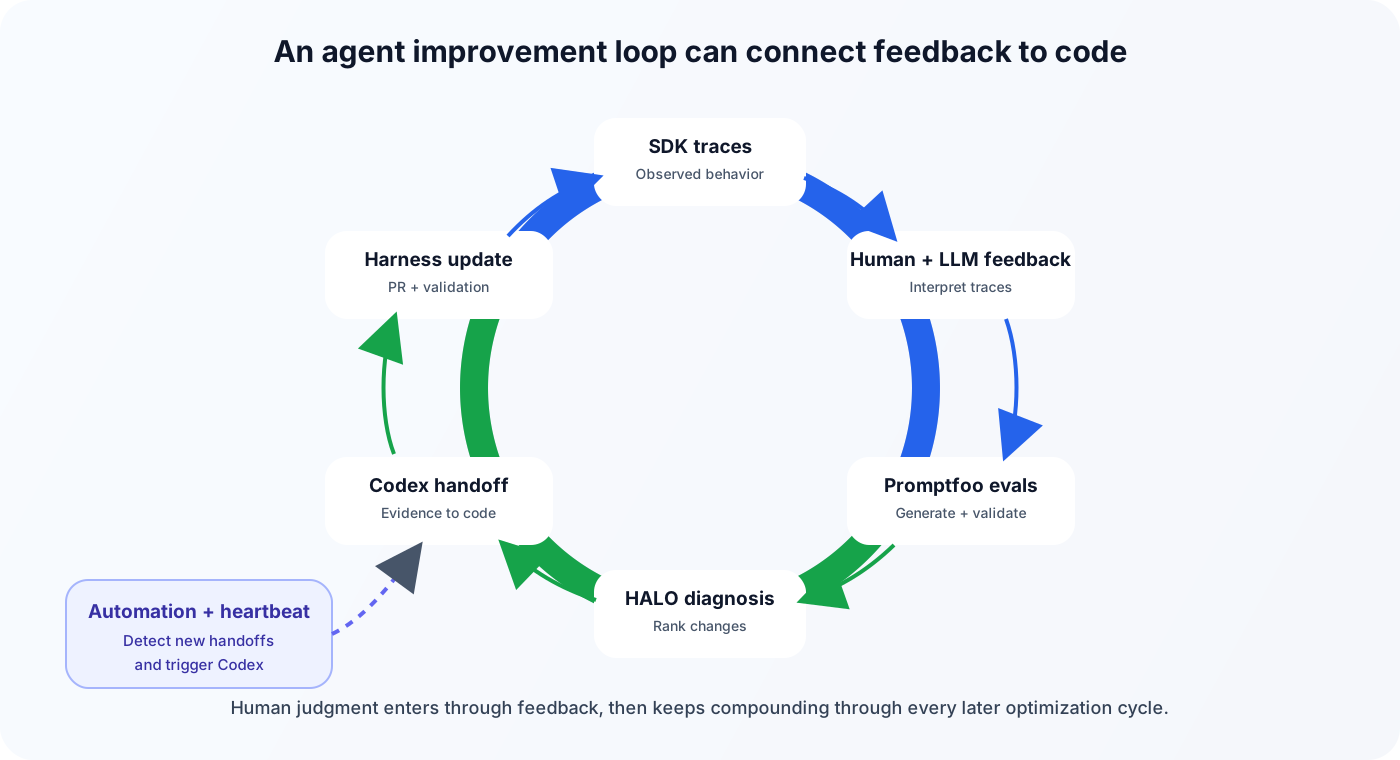 最终,你将拥有:
- 一个基于 OpenAI Agents SDK 的财务分析师,能够跨五次追踪运行审查虚构公司的尽职调查材料
- 针对相同追踪的人工和 LLM 生成的反馈
- 自动生成的 Promptfoo 评估套件
- 针对当前代理行为的 Promptfoo 验证门禁
- 对追踪、反馈和评估结果进行 HALO 优化
- 面向开发者的交接,以便 Codex 实施推荐的框架变更
该代理支持对虚构公司的收购尽职调查。它审查财务导出、客户数据、合同、安全说明、董事会材料和管理层叙述,然后以引用和可审查的工件回答尽职调查问题。
该循环写入一个文件以推进工作:在 ARTIFACT_DIR 下生成的 codex_handoff.md 文件。它包含完整的 HALO 诊断、排名建议、其背后的证据以及 Codex 进行下一次框架更新所需的实施指导。
自动化程度由开发者决定。你可以使用该循环来提出经过审查的变更集,或将其连接到自动打开、合并和部署拉取请求的工作流。常见的起点是经过审查的循环,其中系统提出变更集,开发者在合并前批准差异。随着评估门禁变得更加可信,相同的交接可以支持更深入的自动化。核心工作流在两种情况下都是相同的:追踪加上人工和模型反馈成为具体的框架变更,而不是保持为脱节的评论。
与止步于追踪或评估的示例相比,此笔记本将追踪、审查者判断、生成的评估、优化和实施交接保持在单个可运行的改进循环中。
先决条件
在安装示例所使用的 Python 依赖后,从仓库根目录运行此笔记本:
python -m venv .venv
source .venv/bin/activate
pip install openai openai-agents halo-engine
Promptfoo 通过 npx 运行,因此你还需要在路径中安装带有 npx 的 Node.js。
在运行笔记本之前,请先设置 API 密钥:
export OPENAI_API_KEY=...
该示例特意设计为仅实时运行。轨迹生成、模型评判、评估生成、验证和优化步骤均使用全新的模型输出,因此笔记本展示的是实际循环,而非脚本化预览。下一个单元格将模型选择集中在一处,方便您根据需要替换为更便宜的模型,以在质量与成本之间进行权衡。
默认使用五条轨迹时,完整运行预计需要约20分钟,具体时间会因模型延迟和网络状况而有所波动。耗时最长的部分通常是步骤3(运行追踪到的代理调用)和步骤7(HALO分析整个循环)。反馈、评估生成和Promptfoo单元格也会进行实时调用,但通常耗时较短。长时间运行的单元格会在工作过程中打印进度或已用时间。
%%capture
# Install or upgrade the Python dependencies used by this notebook.
%pip install --quiet --upgrade openai openai-agents halo-engine
from __future__ import annotations

import asyncio
import hashlib
import json
import os
import re
import shutil
import subprocess
import sys
import tempfile
import time
import textwrap
import threading
from contextlib import contextmanager
from dataclasses import asdict, dataclass, field
from datetime import datetime, timezone
from importlib.metadata import version
from pathlib import Path
from typing import Any, Iterable, Iterator, Mapping

from IPython.display import Markdown, display
from openai import OpenAI

def find_project_root(start: Path | None = None) -> Path:
    current = (start or Path.cwd()).resolve()
    for candidate in [current, *current.parents]:
        if (candidate / "registry.yaml").exists():
            return candidate
    return current


PROJECT_ROOT = find_project_root()

if not os.getenv("OPENAI_API_KEY"):
    raise RuntimeError("Set OPENAI_API_KEY before running this live notebook.")
if shutil.which("npx") is None:
    raise RuntimeError("Install Node.js with npx before running the Promptfoo eval gate.")

# Edit these in one place if you want to use lower-cost models for part of the loop.
AGENT_MODEL = os.getenv("OPENAI_AGENT_MODEL", "gpt-5.5")
ANALYSIS_MODEL = os.getenv("OPENAI_ANALYSIS_MODEL", "gpt-5.5")
EVAL_GENERATION_MODEL = os.getenv("OPENAI_EVAL_GENERATION_MODEL", ANALYSIS_MODEL)
JUDGE_MODEL = os.getenv("OPENAI_JUDGE_MODEL", ANALYSIS_MODEL)
HALO_MODEL = os.getenv("OPENAI_HALO_MODEL", ANALYSIS_MODEL)
PROMPTFOO_VERSION = os.getenv("PROMPTFOO_VERSION", "0.121.9")

client = OpenAI()


def format_duration(seconds: float) -> str:
    minutes, remainder = divmod(int(round(seconds)), 60)
    return f"{minutes}m {remainder:02d}s" if minutes else f"{remainder}s"


ARTIFACT_DIR = PROJECT_ROOT / "examples" / "agents_sdk" / "agent_improvement_loop_artifacts"
TRACE_DIR = ARTIFACT_DIR / "traces"
HALO_TRACE_PATH = ARTIFACT_DIR / "halo_traces" / "traces.jsonl"
if ARTIFACT_DIR.exists():
    shutil.rmtree(ARTIFACT_DIR)
ARTIFACT_DIR.mkdir(exist_ok=True)
TRACE_DIR.mkdir(exist_ok=True)
HALO_TRACE_PATH.parent.mkdir(exist_ok=True)

print("Project root detected.")
print("Models:", {
    "agent": AGENT_MODEL,
    "analysis": ANALYSIS_MODEL,
    "eval_generation": EVAL_GENERATION_MODEL,
    "judge": JUDGE_MODEL,
    "halo": HALO_MODEL,
    "promptfoo": PROMPTFOO_VERSION,
})
步骤 1. 创建合成公司数据
该笔记本为一家可能在收购中被审查的公司创建虚构的尽职调查材料。数据混合了结构化导出和叙述性 Markdown 文档,因此代理必须决定哪些来源应获得更多权重。
合成数据中的叙述性 Markdown 文件
| 文件 | 包含原因 |
| --- | --- |
| overview.md | 管理层对公司的高层总结 |
| product_strategy.md | 路线图背景以及未经验证的 NRR 估算 |
| go_to_market.md | 销售动作背景,应与管道数据核对 |
| board_deck.md | 精心制作的管理层叙述,可能与结构化导出冲突 |
| financials/revenue_recognition_notes.md | 启动阶段 ARR 处理的会计背景 |
| legal/contracts_summary.md | 合同层面的风险背景 |
| legal/open_issues.md | 应保持可见的未决法律事项 |
| security/security_overview.md | 安全态势和认证措辞 |
| sales/security_faq.md | 面向销售的安全语言,可能夸大证据 |
| hr/org_chart.md | 领导层和人员配置的运营背景 |
| sales/pipeline_notes.md | 定性管道评论 |
| notes/qa_log.md | 尽职调查问题和未解决的后续事项 |
该示例在运行时生成合成公司数据,因此它保持自包含,同时仍为代理提供结构化导出和叙述性文档的混合体,以便进行分析。
定义合成源文件
下一个折叠单元格包含用于构建虚构公司数据的源文档。
from textwrap import dedent

WORKSPACE_FILES = {
    "overview.md": """
    # FictionalCorp XYZ

    FictionalCorp XYZ is a revenue intelligence software company with annual SaaS subscriptions, usage add-ons, and launch-stage commitments.

    Management reports FY2025 ARR of $43.0M and year-over-year growth of 71%.

    Management reports no legal-entity customer above 15% of booked ARR after excluding launch-stage usage add-ons.

    Legal summary: Management states legal matters are ordinary course and no contract terms should affect valuation.
    """,
    "product_strategy.md": """
    # Product Strategy

    Core product lines:

    - Forecast Assist
    - Pipeline Quality Monitor
    - Renewal Risk Workbench

    Product roadmap priority is enterprise workflow depth. Management expects usage add-ons to increase expansion revenue.

    Sales leadership references a 122% NRR estimate in planning materials, but finance has not published official NRR and the estimate excludes selected downsell and churn adjustments.
    """,
    "go_to_market.md": """
    # Go To Market

    FictionalCorp XYZ sells to CRO and RevOps buyers through a direct sales motion.

    The current plan assumes larger enterprise ACVs and partner-sourced pipeline. Pipeline conversion evidence should be checked against `sales/pipeline.csv`.
    """,
    "board_deck.md": """
    # Board Packet - December 2025

    - FY2025 ending ARR: $43.0M
    - ARR growth: 71%
    - Gross margin: 69%
    - Cash burn: $2.9M per month
    - Runway: 11 months

    Management narrative: the company is positioned for efficient enterprise expansion.

    ARR note: the headline ARR view includes signed launch-stage commitments and a usage true-up view used for board planning.

    Management narrative: customer concentration is manageable when measured by legal entity and booked ARR.
    """,
    "financials/revenue_recognition_notes.md": """
    # Revenue Recognition Notes

    Finance treats `financials/arr_bridge.csv` as the controlled FY2025 ARR bridge.

    The board deck ARR includes $2.8M of signed launch-stage commitments that were not live by 2025-12-31 and $1.1M of usage true-ups that finance does not classify as recurring ARR.

    RevOps also circulates a bookings-adjusted ARR view of $40.8M. That view is useful for pipeline planning but should not be silently reconciled with the controlled ARR bridge.
    """,
    "legal/contracts_summary.md": """
    # Contracts Summary

    Standard customer contracts are annual SaaS agreements with security and DPA exhibits. The largest five customers account for $25.1M of ARR.

    Management summary: legal matters are ordinary course and no contract terms should affect valuation.

    Clause inventory has not been fully reconciled with this summary. Two strategic customer agreements are flagged for non-standard terms in `legal/clause_inventory.csv`.
    """,
    "legal/open_issues.md": """
    # Open Legal Issues

    Former reseller DataHarbor filed a breach-of-contract claim seeking $3.2M plus accelerated commissions. Counsel estimates loss is possible but not probable. A clause review also identified two strategic customer MSAs with non-standard change-of-control notice rights and uncapped confidentiality indemnity language.
    """,
    "security/security_overview.md": """
    # Security Overview

    SOC 2 Type I is complete. SOC 2 Type II fieldwork is in progress, and the Type II report has not been issued.

    Customer security reviews should verify the exact certification status before relying on SOC 2 claims.
    """,
    "sales/security_faq.md": """
    # Sales Security FAQ

    Field guidance says Aurora is "SOC 2 complete" for late-stage enterprise deals.

    Security team note: this wording was intended to refer to Type I readiness, not an issued Type II report. Do not use this FAQ as certification evidence without checking `security/security_overview.md`.
    """,
    "hr/org_chart.md": """
    # Org Chart

    - CEO
    - CFO
    - VP Sales
    - VP Product
    - Head of Security

    Hiring plan assumes 14 net new GTM hires in 2026.
    """,
    "sales/pipeline_notes.md": """
    # Pipeline Notes

    Commit-stage pipeline includes $1.6M of DataHarbor-sourced opportunities that may be affected by the reseller dispute.

    Northstar expansion pipeline assumes completion of SOC 2 Type II before procurement review. Finance has not included this expansion in controlled FY2025 ARR.
    """,
    "notes/qa_log.md": """
    # Diligence Q&A Log

    - NRR was requested. RevOps provided a 122% management estimate, but finance has not validated official NRR and says the estimate excludes downsold Northstar entities and a churned reseller-sourced account.
    - CAC payback was requested but not provided.
    - Top-two customer ARR equals $12.4M, or 34% of FY2025 ARR based on `customers/top_customers.csv`.
    - Northstar Holdings parent-account ARR equals $12.4M, or 34% of FY2025 ARR based on `customers/account_hierarchy.csv`.
    - Board ARR should not be silently reconciled to finance ARR; use `financials/revenue_recognition_notes.md` for the difference.
    """,
    "financials/arr_bridge.csv": """
    metric,value_m
    opening_arr_2025_m,21.58
    new_arr_m,8.1
    expansion_arr_m,3.2
    contraction_arr_m,1.1
    churn_arr_m,2.7
    ending_arr_2025_m,36.9
    bookings_adjusted_arr_m,40.8
    """,
    "financials/monthly_kpis.csv": """
    month,ending_arr_m,new_arr_m,expansion_arr_m,churn_arr_m,gross_margin
    2025-01,21.58,0.55,0.35,0.18,0.69
    2025-02,23.28,0.59,0.37,0.20,0.69
    2025-03,24.98,0.63,0.39,0.21,0.69
    2025-04,26.69,0.67,0.41,0.22,0.69
    2025-05,28.39,0.71,0.43,0.24,0.69
    2025-06,30.09,0.75,0.45,0.26,0.69
    2025-07,31.79,0.79,0.47,0.27,0.69
    2025-09,33.50,0.83,0.49,0.28,0.69
    2025-10,35.20,0.87,0.51,0.30,0.69
    2025-12,36.90,0.91,0.53,0.32,0.69
    """,
    "financials/p_and_l.csv": """
    period,revenue_m,gross_margin,opex_m,cash_burn_m,runway_months
    FY2025,30.26,0.69,47.71,2.9,11
    """,
    "financials/retention_extract.csv": """
    metric,value,status,notes
    net_revenue_retention,122%,management_estimate_unvalidated,Sales deck estimate; excludes downsold Northstar entities and one churned reseller-sourced account.
    gross_revenue_retention,84%,finance_partial,Preliminary 2025 cohort; usage feeds incomplete for two enterprise customers.
    logo_retention,91%,finance_partial,"Includes legal entities, not parent-account rollups."
    cac_payback_months,,not_provided,Requested by diligence team; no source schedule in dataroom.
    """,
    "customers/top_customers.csv": """
    customer,parent_account,arr_m,arr_share,segment,renewal_date,inclusion_basis
    Northstar Bank,Northstar Holdings,7.8,0.2114,Enterprise,2026-02-15,controlled_arr_bridge
    Northstar Capital Markets,Northstar Holdings,4.6,0.1247,Enterprise,2026-04-01,controlled_arr_bridge
    Helio Retail,Helio Retail,6.9,0.1870,Enterprise,2026-05-15,controlled_arr_bridge
    BluePeak Logistics,BluePeak Logistics,3.6,0.0976,Mid-market,2026-06-30,controlled_arr_bridge
    Summit Foods,Summit Foods,2.2,0.0596,Mid-market,2026-02-28,controlled_arr_bridge
    """,
    "customers/account_hierarchy.csv": """
    legal_entity,parent_account,parent_arr_m,note
    Northstar Bank,Northstar Holdings,12.4,Same procurement parent as Northstar Capital Markets.
    Northstar Capital Markets,Northstar Holdings,12.4,Managed by separate RevOps owner but same parent renewal committee.
    Helio Retail,Helio Retail,6.9,Standalone parent account.
    BluePeak Logistics,BluePeak Logistics,3.6,Standalone parent account; renewal issue open.
    """,
    "customers/renewal_calendar.csv": """
    customer,renewal_date,renewal_risk,notes
    Northstar Bank,2026-02-15,medium,Expansion depends on completed SOC 2 Type II.
    Northstar Capital Markets,2026-04-01,medium,Same parent procurement committee as Northstar Bank.
    Helio Retail,2026-05-15,medium,Adoption below plan; forecast latency escalation remains in monitoring.
    BluePeak Logistics,2026-06-30,high,Open CRM sync errors and renewal risk.
    """,
    "customers/customer_health.csv": """
    customer,health,primary_risk,signal_date,caveat
    Northstar Bank,green,none flagged,2025-10-31,"Northstar health is recorded by legal entity, not parent account."
    Northstar Capital Markets,yellow,monitor adoption,2025-10-31,"Northstar health is recorded by legal entity, not parent account."
    Helio Retail,yellow,monitor adoption,2025-12-15,
    BluePeak Logistics,red,renewal risk,2025-12-15,
    Summit Foods,yellow,monitor adoption,2025-12-15,
    """,
    "legal/clause_inventory.csv": """
    customer,issue,exposure,confidence
    Northstar Bank,change_of_control_notice,customer may request transition plan within 10 days of a control transaction,medium
    Helio Retail,uncapped_confidentiality_indemnity,uncapped liability for confidentiality breach; not reflected in management summary,high
    BluePeak Logistics,service_credit_carveout,credits can exceed one month fees if CRM sync SLA missed for two consecutive months,medium
    """,
    "sales/pipeline.csv": """
    stage,pipeline_m,historical_close_rate,quality_note
    commit,6.1,0.39,Includes security-dependent Northstar expansion.
    best_case,9.7,0.28,Includes DataHarbor-sourced opportunities under dispute.
    early,18.2,0.08,High volume but low conversion quality.
    """,
    "support/escalations.csv": """
    customer,severity,issue,status
    Northstar Capital Markets,medium,Forecast latency,monitoring
    BluePeak Logistics,high,CRM sync errors,open
    Northstar Bank,medium,Security questionnaire blocked pending SOC 2 Type II report,open
    """,
}
物化合成数据
将源文件写入磁盘,添加清单,并检查生成的数据集。
def write_workspace_file(path: Path, content: str) -> None:
    path.parent.mkdir(parents=True, exist_ok=True)
    path.write_text(dedent(content).strip() + "\n", encoding="utf-8")


def generate_acquisition_diligence_workspace() -> Path:
    """Create the synthetic acquisition-diligence workspace directly from notebook data."""
    dataroom = ARTIFACT_DIR / "synthetic_dataroom"
    shutil.rmtree(dataroom, ignore_errors=True)
    for relative_path, content in WORKSPACE_FILES.items():
        write_workspace_file(dataroom / relative_path, content)
    manifest = {
        "company_name": "FictionalCorp XYZ",
        "scenario": "adversarial_diligence",
        "files": sorted(str(path.relative_to(dataroom)) for path in dataroom.rglob("*") if path.is_file()),
    }
    write_workspace_file(dataroom / "manifest.json", json.dumps(manifest, indent=2))
    return dataroom


dataset = generate_acquisition_diligence_workspace()
files = sorted(str(path.relative_to(dataset)) for path in dataset.rglob("*") if path.is_file())
print(f"Dataset created: {len(files)} files")
步骤 2. 定义基于 Agents SDK 的分析代理
该示例代理对一家虚构的 SaaS 公司进行收购尽职调查,该公司正在被评估为可能的收购目标。案例材料包含结构化导出和管理层叙述。一些来源一致,一些冲突,一些重要声明仅得到部分支持。这为我们提供了现实的理由来逐步改进测试平台。
代理仅使用提供的公司数据回答投资团队的问题。当结构化财务证据与叙述摘要不一致时,应优先采用结构化财务证据;当证据缺失时,应保留不确定性;并留下可供其他审查者检查的工件。
OpenAI Agents SDK 提供了此工作流所需的托管运行器、沙箱执行、模型设置和追踪钩子。提示、工具、路由规则、输出要求和验证检查共同构成了当前的代理测试平台。
代理生成的工件
| 工件 | 代理写入原因 |
| --- | --- |
| summary_answer.md | 返回给用户的简洁答案 |
| investment_memo.md | 供尽职调查读者使用的更完整审查工件 |
| risk_register.json | 带有证据的结构化风险,下游系统可检查 |
| open_questions.md | 缺失的证据或未解决的问题,应保持可见 |
| citations.json | 从声明到源文件的机器可读链接 |
| evidence_table.csv | 声明和支持来源的表格化审计跟踪 |
这些工件通过保留支持证据、未解决的问题和所需文件,使工作可审查,与最终答案一起。
需要关注的失败模式
本笔记本旨在揭示以下失败模式:
- 当结构化导出不一致时,将管理层叙述视为官方指标
- 报告未经财务验证的 NRR 估计,仿佛财务已确认
- 将母公司账户集中度合并为较弱的法人实体视图
- 当证据仅支持 Type I 时,声称“SOC 2 完成”
- 生成精美的答案,但留下不完整的引用、风险文件或证据工件
定义测试框架模式
从模型设置和提升代理配置的小型数据结构开始。这些使测试框架明确,以便后续优化可以针对不仅仅是提示措辞的内容。
@dataclass(frozen=True)
class ModelSettings:
    agent_model: str
    reasoning_effort: str


@dataclass(frozen=True)
class AgentConfig:
    version: str
    system_prompt: str
    model_settings: ModelSettings
    tool_policy: dict[str, Any]
    eval_metadata: dict[str, Any]
    path: Path = field(default_factory=lambda: Path("notebook_defined_agent_config"))

    @property
    def required_artifacts(self) -> list[str]:
        return self.tool_policy["required_artifacts"]

    def build_instructions(self) -> str:
        return "\n\n".join([
            self.system_prompt,
            format_policy_section("Tool policy", self.tool_policy),
            f"Runtime config:\n- Config version: `{self.version}`.\n- Treat this config as the promoted runtime contract.\n- Do not modify the runtime config during the run.",
        ]) + "\n"


def format_policy_section(title: str, policy: dict[str, Any]) -> str:
    lines = [f"{title}:"]
    for key, value in policy.items():
        lines.extend(format_policy_value(key, value))
    return "\n".join(lines)


def format_policy_value(key: str, value: Any, indent: int = 0) -> list[str]:
    prefix = "  " * indent
    if isinstance(value, dict):
        lines = [f"{prefix}- {key}:"]
        for child_key, child_value in value.items():
            lines.extend(format_policy_value(child_key, child_value, indent + 1))
        return lines
    if isinstance(value, list):
        lines = [f"{prefix}- {key}:"]
        for item in value:
            if isinstance(item, dict):
                lines.append(f"{prefix}  -")
                for child_key, child_value in item.items():
                    lines.extend(format_policy_value(child_key, child_value, indent + 2))
            else:
                lines.append(f"{prefix}  - {item}")
        return lines
    return [f"{prefix}- {key}: {value}"]
配置指令与策略
系统提示中规定了证据规则,工具策略定义了代理可以读取和写入的内容,而评估元数据则记录了当前推广的测试框架版本。
SYSTEM_PROMPT = """
You are a diligence analyst reviewing a synthetic company dataroom.

Evidence scope:
- Use only files under `data/`.
- Do not use outside knowledge or assumptions.
- Prefer structured CSV/JSON exports over narrative files when they conflict.

Runtime tools:
- The sandbox starts in the mounted workspace root. Use workspace-relative paths such as `data/...` and `outputs/...`; when running shell commands, omit `workdir` or use a relative path only. Never pass absolute temporary paths.
- `data/tools/check_evidence_coverage.py`: use this before finalizing answers with material claims. Create a JSON list of claims with `claim`, `claim_type`, and `citations`, then run `python data/tools/check_evidence_coverage.py --claims-json <path> --dataset-root data --output outputs/evidence_coverage.json`.
- `data/tools/validate_output_contract.py`: run this after writing the required artifacts and before final response with `python data/tools/validate_output_contract.py --outputs outputs --dataset-root data --output outputs/output_contract_validation.json`.
- If either tool reports unsupported claims, missing citations, missing files, malformed JSON, or empty artifacts, revise the answer/artifacts before finalizing. If the evidence is unavailable, say the claim is unknown or unsupported.

Citation rules:
- Every material claim must cite one or more source filenames.
- Cite filenames exactly as workspace-relative paths, for example `financials/arr_bridge.csv`.
- Do not cite files that do not support the claim.

Unknown-handling rules:
- If evidence is missing, state that the answer is unknown or unsupported.
- Never fabricate missing numbers.
- If evidence conflicts, state the conflict explicitly instead of reconciling silently.

Output rules:
- Write `outputs/summary_answer.md`.
- Write `outputs/investment_memo.md`.
- Write `outputs/risk_register.json`.
- Write `outputs/open_questions.md`.
- Write `outputs/citations.json`.
- Write `outputs/evidence_table.csv`.
""".strip()

MODEL_SETTINGS = {
    "agent_model": AGENT_MODEL,
    "reasoning_effort": "medium",
}

TOOL_POLICY = {
    "allowed_data_root": "data",
    "writable_output_root": "outputs",
    "required_artifacts": [
        "summary_answer.md",
        "investment_memo.md",
        "risk_register.json",
        "open_questions.md",
        "citations.json",
        "evidence_table.csv",
    ],
    "evidence_preference": [
        "Prefer structured CSV or JSON exports over narrative summaries when sources conflict.",
        "Treat board materials as useful narrative evidence, not the final system of record for metrics.",
        "Surface unresolved conflicts instead of silently reconciling them.",
    ],
    "runtime_tools": [
        {
            "path": "data/tools/check_evidence_coverage.py",
            "purpose": "Audit drafted material claims against cited dataroom files before final answer.",
            "recommended_command": "python data/tools/check_evidence_coverage.py --claims-json outputs/claim_audit_input.json --dataset-root data --output outputs/evidence_coverage.json",
        },
        {
            "path": "data/tools/validate_output_contract.py",
            "purpose": "Validate required output artifacts, JSON shape, and citation/source file references.",
            "recommended_command": "python data/tools/validate_output_contract.py --outputs outputs --dataset-root data --output outputs/output_contract_validation.json",
        },
    ],
    "unknown_handling": [
        "Say unknown or unsupported when a metric is absent.",
        "Do not infer missing values from adjacent metrics.",
        "Keep facts, inferences, and open questions separate.",
    ],
    "mutation_policy": [
        "Write only to the configured outputs directory.",
        "Do not modify dataroom inputs.",
        "Do not modify runtime agent configuration during a run.",
    ],
}

EVAL_METADATA = {
    "version": "v001",
    "status": "promoted",
    "created_by": "manual_baseline",
    "promotion_gate": "manual_review",
    "description": "Baseline diligence analyst config with strict dataroom grounding, citation, unknown-handling, and artifact rules.",
}

agent_config = AgentConfig(
    version=EVAL_METADATA["version"],
    system_prompt=SYSTEM_PROMPT,
    model_settings=ModelSettings(**MODEL_SETTINGS),
    tool_policy=TOOL_POLICY,
    eval_metadata=EVAL_METADATA,
)
检查代理配置
这个紧凑视图显示了提升的配置版本、选定的模型、必需的工件以及代理可以使用的运行时工具。
required_artifacts_md = "\n".join(
    f"- `{artifact}`" for artifact in agent_config.required_artifacts
)
runtime_tools_md = "\n".join(
    f"- `{tool['path']}` — {tool['purpose']}"
    for tool in agent_config.tool_policy["runtime_tools"]
)

display(Markdown(f"""
### Agent config summary

- **Version:** `{agent_config.version}`
- **Agent model:** `{agent_config.model_settings.agent_model}`
- **Reasoning effort:** `{agent_config.model_settings.reasoning_effort}`

**Required artifacts**
{required_artifacts_md}

**Runtime tools**
{runtime_tools_md}
"""))
添加验证工具
接下来的辅助函数在工作区内创建两个本地工具:一个检查草拟的声明是否引用了真实的数据室文件,另一个验证所需的输出工件是否存在且具有预期的形状。代码默认隐藏以节省空间,但如果您想检查实现,可以展开它。
CHECK_EVIDENCE_COVERAGE = r'''#!/usr/bin/env python3

import argparse
import json
from pathlib import Path


def main() -> None:
    parser = argparse.ArgumentParser(description="Audit whether drafted claims cite existing dataroom files.")
    parser.add_argument("--claims-json", type=Path, required=True)
    parser.add_argument("--dataset-root", type=Path, default=Path("data"))
    parser.add_argument("--output", type=Path, default=Path("outputs/evidence_coverage.json"))
    args = parser.parse_args()

    claims = json.loads(args.claims_json.read_text(encoding="utf-8"))
    if not isinstance(claims, list):
        raise ValueError("--claims-json must contain a JSON list of claim objects")

    result = check_evidence_coverage(claims, args.dataset_root)
    args.output.parent.mkdir(parents=True, exist_ok=True)
    args.output.write_text(json.dumps(result, indent=2) + "\n", encoding="utf-8")
    print(json.dumps(result, indent=2))


def check_evidence_coverage(claims: list[dict], dataset_root: Path) -> dict:
    supported = []
    unsupported = []
    missing_citations = []

    for raw in claims:
        claim = str(raw.get("claim") or "").strip()
        claim_type = str(raw.get("claim_type") or "claim")
        citations = [str(item).strip().removeprefix("data/") for item in raw.get("citations") or [] if str(item).strip()]
        row = {"claim": claim, "claim_type": claim_type, "citations": citations}
        if not citations:
            missing_citations.append({**row, "issue": "No citation provided."})
            continue
        missing = [citation for citation in citations if not (dataset_root / citation).exists()]
        if missing:
            unsupported.append({**row, "issue": f"Missing cited file(s): {', '.join(missing)}"})
        else:
            supported.append(row)

    return {
        "supported_claims": supported,
        "unsupported_claims": unsupported,
        "missing_citations": missing_citations,
        "recommended_caveats": [
            "Add valid source filenames or mark unsupported claims as unknown before final answer."
        ],
        "passed": not unsupported and not missing_citations,
    }


if __name__ == "__main__":
    main()
'''


VALIDATE_OUTPUT_CONTRACT = r'''#!/usr/bin/env python3

import argparse
import csv
import json
from pathlib import Path


REQUIRED_FILES = [
    "summary_answer.md",
    "investment_memo.md",
    "risk_register.json",
    "open_questions.md",
    "citations.json",
    "evidence_table.csv",
]


def main() -> None:
    parser = argparse.ArgumentParser(description="Validate diligence output artifacts before final answer.")
    parser.add_argument("--outputs", type=Path, default=Path("outputs"))
    parser.add_argument("--dataset-root", type=Path, default=Path("data"))
    parser.add_argument("--output", type=Path, default=Path("outputs/output_contract_validation.json"))
    args = parser.parse_args()

    result = validate_output_contract(args.outputs, args.dataset_root)
    args.output.parent.mkdir(parents=True, exist_ok=True)
    args.output.write_text(json.dumps(result, indent=2) + "\n", encoding="utf-8")
    print(json.dumps(result, indent=2))


def validate_output_contract(outputs: Path, dataset_root: Path) -> dict:
    issues = []
    for filename in REQUIRED_FILES:
        path = outputs / filename
        if not path.exists():
            issues.append({"file": filename, "issue": "missing required artifact"})
        elif path.stat().st_size == 0:
            issues.append({"file": filename, "issue": "empty required artifact"})

    risks = _read_json(outputs / "risk_register.json", default=[])
    citations = _read_json(outputs / "citations.json", default=[])
    if not isinstance(risks, list):
        issues.append({"file": "risk_register.json", "issue": "must be a JSON list"})
        risks = []
    if not isinstance(citations, list):
        issues.append({"file": "citations.json", "issue": "must be a JSON list"})
        citations = []

    for index, risk in enumerate(risks):
        evidence = risk.get("evidence") if isinstance(risk, dict) else None
        if not evidence:
            issues.append({"file": "risk_register.json", "risk_index": index, "issue": "risk lacks evidence"})
            continue
        missing = [str(item).removeprefix("data/") for item in evidence if not (dataset_root / str(item).removeprefix("data/")).exists()]
        if missing:
            issues.append({"file": "risk_register.json", "risk_index": index, "issue": f"missing evidence file(s): {', '.join(missing)}"})

    for index, citation in enumerate(citations):
        sources = citation.get("sources") if isinstance(citation, dict) else None
        if not sources:
            issues.append({"file": "citations.json", "citation_index": index, "issue": "citation lacks sources"})
            continue
        missing = [str(item).removeprefix("data/") for item in sources if not (dataset_root / str(item).removeprefix("data/")).exists()]
        if missing:
            issues.append({"file": "citations.json", "citation_index": index, "issue": f"missing source file(s): {', '.join(missing)}"})

    try:
        with (outputs / "evidence_table.csv").open(newline="", encoding="utf-8") as handle:
            rows = list(csv.DictReader(handle))
        if rows and not {"claim_id", "claim", "sources"}.issubset(rows[0].keys()):
            issues.append({"file": "evidence_table.csv", "issue": "must include claim_id, claim, and sources columns"})
    except FileNotFoundError:
        pass

    return {"passed": not issues, "issues": issues, "required_files": REQUIRED_FILES}


def _read_json(path: Path, default):
    if not path.exists():
        return default
    try:
        return json.loads(path.read_text(encoding="utf-8"))
    except json.JSONDecodeError as exc:
        return {"error": str(exc)}


if __name__ == "__main__":
    main()
'''


def write_runtime_tools(dataset_dir: Path) -> list[str]:
    tools_dir = dataset_dir / "tools"
    tools_dir.mkdir(parents=True, exist_ok=True)
    files = {
        "check_evidence_coverage.py": CHECK_EVIDENCE_COVERAGE,
        "validate_output_contract.py": VALIDATE_OUTPUT_CONTRACT,
    }
    written: list[str] = []
    for filename, content in files.items():
        path = tools_dir / filename
        path.write_text(content, encoding="utf-8")
        path.chmod(0o755)
        written.append(str(path.relative_to(dataset_dir)))
    return written
构建每个用户轮次
提示构建器仅在需要时添加任务特定的指导,例如备忘录格式、单独的风险类别,或对不支持的NRR声明的严格处理。
def build_user_prompt(question: str, agent_config: Any | None = None) -> str:
    config_line = ""
    if agent_config is not None:
        config_line = f"\nActive agent config: `{agent_config.version}` from `{agent_config.path}`.\n"
    memo_instruction = ""
    if _asks_for_memo(question):
        memo_instruction = (
            "\nThe user asked for a memo-style deliverable. Return the memo content inline in "
            "your final answer and also write the required output artifacts. Do not answer only "
            "with a status update or artifact path list.\n"
        )
    risk_category_instruction = ""
    if _asks_for_top_risk_categories(question):
        risk_category_instruction = (
            "\nStructure the final answer with separate sections for Financial, Legal, and "
            "Customer concentration risks. Do not collapse customer concentration into the "
            "financial category.\n"
        )
    unsupported_metric_instruction = ""
    if _asks_for_net_revenue_retention(question):
        unsupported_metric_instruction = (
            "\nFor net revenue retention, report the metric only if the dataroom directly "
            "provides NRR/net revenue retention. Do not derive or estimate an NRR percentage "
            "from ARR bridge components unless the user explicitly asks for an estimate. If "
            "the metric is absent, say it is unknown or unsupported, cite the searched "
            "source files, and separate missing evidence from any directional inference.\n"
        )
    return f"""
Answer this diligence question using only the mounted dataroom:

{question}
{config_line}
{memo_instruction}
{risk_category_instruction}
{unsupported_metric_instruction}
Also write the required output artifacts. Keep the answer concise, grounded, and citation-heavy.
Use workspace-relative paths for shell commands and omit `workdir`; do not pass absolute temporary paths.
"""


def _asks_for_memo(question: str) -> bool:
    lower = question.lower()
    return "memo" in lower or "ic-style" in lower or "investment committee" in lower


def _asks_for_top_risk_categories(question: str) -> bool:
    lower = question.lower()
    return all(term in lower for term in ("financial", "legal", "customer")) and "risk" in lower


def _asks_for_net_revenue_retention(question: str) -> bool:
    lower = question.lower()
    return "net revenue retention" in lower or "nrr" in lower
导出追踪以供后续优化
本地导出器将 Agents SDK 事件转换为 HALO 稍后可以读取的 OpenTelemetry 风格 JSONL。由于其实现较为复杂,代码默认保持折叠状态。
配置追踪导出器
设置导出器对象,用于接收 Agents SDK 的 spans,并为每个 span 写入一行 JSONL。
EXPORT_SCHEMA_VERSION = 1

OBSERVATION_KIND_BY_TYPE = {
    "agent": "AGENT",
    "generation": "LLM",
    "response": "LLM",
    "function": "TOOL",
    "mcp_tools": "TOOL",
    "handoff": "CHAIN",
    "guardrail": "GUARDRAIL",
    "custom": "SPAN",
    "task": "SPAN",
    "turn": "SPAN",
    "transcription": "SPAN",
    "speech": "SPAN",
    "speech_group": "SPAN",
}


@dataclass(frozen=True)
class HaloExportContext:
    project_id: str
    service_name: str
    service_version: str | None = None
    deployment_environment: str | None = None
    extra_resource_attributes: Mapping[str, Any] | None = None


def setup_halo_tracing(
    path: str | Path,
    *,
    project_id: str = "synthetic-dataroom-agent",
    service_name: str = "financial-diligence-analyst",
    service_version: str | None = None,
    deployment_environment: str | None = None,
    extra_resource_attributes: Mapping[str, Any] | None = None,
):
    from agents import set_trace_processors

    trace_path = Path(path)
    trace_path.parent.mkdir(parents=True, exist_ok=True)
    processor = HaloJsonlTraceProcessor(
        trace_path,
        ctx=HaloExportContext(
            project_id=project_id,
            service_name=service_name,
            service_version=service_version,
            deployment_environment=deployment_environment,
            extra_resource_attributes=extra_resource_attributes,
        ),
    )
    # Use only the local exporter for this cookbook workflow.
    # Hosted trace ingestion may be unavailable in some environments (for example ZDR orgs).
    set_trace_processors([processor])
    return processor


class HaloJsonlTraceProcessor:
    def __init__(self, path: Path, *, ctx: HaloExportContext):
        self._path = path
        self._ctx = ctx
        self._lock = threading.Lock()
        self._handle = path.open("a", encoding="utf-8")
        self._trace_meta: dict[str, tuple[str | None, str | None, dict[str, Any]]] = {}

    def on_trace_start(self, trace) -> None:  # noqa: ANN001
        data = trace.export() or {}
        trace_id = _strip_prefix(data.get("id"), "trace_") or ""
        metadata = data.get("metadata") if isinstance(data.get("metadata"), dict) else {}
        self._trace_meta[trace_id] = (
            data.get("workflow_name"),
            data.get("group_id"),
            metadata,
        )

    def on_trace_end(self, trace) -> None:  # noqa: ANN001
        data = trace.export() or {}
        trace_id = _strip_prefix(data.get("id"), "trace_") or ""
        self._trace_meta.pop(trace_id, None)

    def on_span_start(self, span) -> None:  # noqa: ANN001
        return None

    def on_span_end(self, span) -> None:  # noqa: ANN001
        exported = span.export() or {}
        trace_id = _strip_prefix(exported.get("trace_id"), "trace_") or ""
        workflow_name, group_id, trace_metadata = self._trace_meta.get(trace_id, (None, None, {}))
        line = span_to_halo_jsonl_line(
            span,
            ctx=self._ctx,
            workflow_name=workflow_name,
            group_id=group_id,
            trace_metadata=trace_metadata,
        )
        encoded = json.dumps(line, separators=(",", ":"), ensure_ascii=False, default=str)
        with self._lock:
            self._handle.write(encoded)
            self._handle.write("\n")

    def shutdown(self) -> None:
        with self._lock:
            try:
                self._handle.flush()
                self._handle.close()
            except Exception:
                pass

    def force_flush(self) -> None:
        with self._lock:
            self._handle.flush()
将 SDK spans 映射为 HALO 可读字段
这些辅助函数会将每种 SDK span 类型转换为 HALO 稍后要检查的属性。
def span_to_halo_jsonl_line(
    span,
    *,
    ctx: HaloExportContext,
    workflow_name: str | None = None,
    group_id: str | None = None,
    trace_metadata: Mapping[str, Any] | None = None,
) -> dict[str, Any]:
    raw = span.export() or {}
    span_data = raw.get("span_data") or {}
    span_type = str(span_data.get("type") or "custom")
    error = raw.get("error")
    resource_attributes: dict[str, Any] = {"service.name": ctx.service_name}
    if ctx.service_version:
        resource_attributes["service.version"] = ctx.service_version
    if ctx.deployment_environment:
        resource_attributes["deployment.environment"] = ctx.deployment_environment
    if ctx.extra_resource_attributes:
        resource_attributes.update(ctx.extra_resource_attributes)

    attributes, projection = _attributes_for_span_type(span_type, span_data)
    if workflow_name:
        attributes["agent.workflow.name"] = workflow_name
    if group_id:
        attributes["agent.workflow.group_id"] = group_id
    for key, value in (trace_metadata or {}).items():
        if _json_safe(value):
            attributes[f"agent.trace_metadata.{key}"] = value
        else:
            attributes[f"agent.trace_metadata.{key}"] = _json(value)

    attributes.update(
        {
            "inference.export.schema_version": EXPORT_SCHEMA_VERSION,
            "inference.project_id": ctx.project_id,
            "inference.observation_kind": OBSERVATION_KIND_BY_TYPE.get(span_type, "SPAN"),
            "inference.llm.provider": projection.get("llm_provider"),
            "inference.llm.model_name": projection.get("llm_model_name"),
            "inference.llm.input_tokens": projection.get("input_tokens"),
            "inference.llm.output_tokens": projection.get("output_tokens"),
            "inference.llm.cost.total": projection.get("cost_total"),
            "inference.user_id": projection.get("user_id"),
            "inference.session_id": group_id,
            "inference.agent_name": projection.get("agent_name") or "",
        }
    )

    return {
        "trace_id": _strip_prefix(raw.get("trace_id"), "trace_") or "",
        "span_id": _strip_prefix(raw.get("id"), "span_") or "",
        "parent_span_id": _strip_prefix(raw.get("parent_id"), "span_") or "",
        "trace_state": "",
        "name": _span_name(span_type, span_data),
        "kind": _span_kind(span_type),
        "start_time": _to_otlp_timestamp(raw.get("started_at")),
        "end_time": _to_otlp_timestamp(raw.get("ended_at")),
        "status": {
            "code": "STATUS_CODE_ERROR" if error else "STATUS_CODE_OK",
            "message": str((error or {}).get("message") or ""),
        },
        "resource": {"attributes": resource_attributes},
        "scope": {"name": "openai-agents-sdk", "version": _sdk_version()},
        "attributes": {key: value for key, value in attributes.items() if value is not None},
    }


def _attributes_for_span_type(
    span_type: str,
    data: Mapping[str, Any],
) -> tuple[dict[str, Any], dict[str, Any]]:
    if span_type == "agent":
        return _agent_attrs(data)
    if span_type == "generation":
        return _generation_attrs(data)
    if span_type == "response":
        return _response_attrs(data)
    if span_type == "function":
        return _function_attrs(data)
    if span_type == "mcp_tools":
        return _mcp_tools_attrs(data)
    if span_type == "handoff":
        return _handoff_attrs(data)
    if span_type == "guardrail":
        return _guardrail_attrs(data)
    return _custom_attrs(span_type, data)


def _agent_attrs(data: Mapping[str, Any]) -> tuple[dict[str, Any], dict[str, Any]]:
    name = data.get("name") or ""
    return _drop_none(
        {
            "openinference.span.kind": "AGENT",
            "agent.name": name,
            "agent.handoffs": _json(data.get("handoffs")),
            "agent.tools": _json(data.get("tools")),
            "agent.output_type": data.get("output_type"),
        }
    ), {"agent_name": name}


def _generation_attrs(data: Mapping[str, Any]) -> tuple[dict[str, Any], dict[str, Any]]:
    usage = data.get("usage") or {}
    input_messages = data.get("input") or []
    output_messages = data.get("output") or []
    attrs: dict[str, Any] = {
        "openinference.span.kind": "LLM",
        "llm.provider": "openai",
        "llm.model_name": data.get("model"),
        "llm.invocation_parameters": _json(data.get("model_config")),
        "llm.input_messages": _json(list(input_messages)),
        "llm.output_messages": _json(list(output_messages)),
        "llm.token_count.prompt": _int(usage.get("input_tokens") or usage.get("prompt_tokens")),
        "llm.token_count.completion": _int(
            usage.get("output_tokens") or usage.get("completion_tokens")
        ),
        "llm.token_count.total": _int(usage.get("total_tokens")),
    }
    attrs.update(_expand_messages("llm.input_messages", input_messages))
    attrs.update(_expand_messages("llm.output_messages", output_messages))
    return _drop_none(attrs), {
        "llm_provider": "openai",
        "llm_model_name": data.get("model"),
        "input_tokens": _int(usage.get("input_tokens") or usage.get("prompt_tokens")),
        "output_tokens": _int(usage.get("output_tokens") or usage.get("completion_tokens")),
    }


def _response_attrs(data: Mapping[str, Any]) -> tuple[dict[str, Any], dict[str, Any]]:
    usage = data.get("usage") or {}
    return _drop_none(
        {
            "openinference.span.kind": "LLM",
            "llm.provider": "openai",
            "llm.response.id": data.get("response_id"),
            "llm.token_count.prompt": _int(usage.get("input_tokens") or usage.get("prompt_tokens")),
            "llm.token_count.completion": _int(
                usage.get("output_tokens") or usage.get("completion_tokens")
            ),
            "llm.token_count.total": _int(usage.get("total_tokens")),
        }
    ), {
        "llm_provider": "openai",
        "input_tokens": _int(usage.get("input_tokens") or usage.get("prompt_tokens")),
        "output_tokens": _int(usage.get("output_tokens") or usage.get("completion_tokens")),
    }


def _function_attrs(data: Mapping[str, Any]) -> tuple[dict[str, Any], dict[str, Any]]:
    return _drop_none(
        {
            "openinference.span.kind": "TOOL",
            "tool.name": data.get("name"),
            "input.value": data.get("input"),
            "output.value": data.get("output"),
            "mcp.data": _json(data.get("mcp_data")),
        }
    ), {}


def _mcp_tools_attrs(data: Mapping[str, Any]) -> tuple[dict[str, Any], dict[str, Any]]:
    return _drop_none(
        {
            "openinference.span.kind": "TOOL",
            "mcp.server": data.get("server"),
            "mcp.tools.listed": _json(data.get("result")),
        }
    ), {}


def _handoff_attrs(data: Mapping[str, Any]) -> tuple[dict[str, Any], dict[str, Any]]:
    return _drop_none(
        {
            "openinference.span.kind": "CHAIN",
            "agent.handoff.from": data.get("from_agent"),
            "agent.handoff.to": data.get("to_agent"),
        }
    ), {"agent_name": data.get("to_agent")}


def _guardrail_attrs(data: Mapping[str, Any]) -> tuple[dict[str, Any], dict[str, Any]]:
    return _drop_none(
        {
            "openinference.span.kind": "GUARDRAIL",
            "guardrail.name": data.get("name"),
            "guardrail.triggered": bool(data.get("triggered")),
        }
    ), {}


def _custom_attrs(span_type: str, data: Mapping[str, Any]) -> tuple[dict[str, Any], dict[str, Any]]:
    attrs: dict[str, Any] = {
        "openinference.span.kind": "CHAIN",
        "sdk.span.type": span_type,
    }
    if data.get("name"):
        attrs["sdk.span.name"] = data.get("name")
    payload = data.get("data") or {}
    if isinstance(payload, Mapping):
        for key, value in payload.items():
            attrs[f"sdk.data.{key}"] = value if _json_safe(value) else _json(value)
    if "usage" in data:
        attrs["llm.token_count.total"] = _int((data.get("usage") or {}).get("total_tokens"))
    return _drop_none(attrs), {}
规范化辅助值
最终的辅助函数确保导出的跨度中 ID、时间戳和序列化值保持一致。
def _strip_prefix(value: Any, prefix: str) -> str | None:
    if not value:
        return None
    text = str(value)
    return text[len(prefix) :] if text.startswith(prefix) else text


def _to_otlp_timestamp(value: str | None) -> str:
    if not value:
        return ""
    parsed = datetime.fromisoformat(value)
    if parsed.tzinfo is None:
        parsed = parsed.replace(tzinfo=timezone.utc)
    parsed = parsed.astimezone(timezone.utc)
    return parsed.strftime("%Y-%m-%dT%H:%M:%S.") + f"{parsed.microsecond:06d}000Z"


def _span_kind(span_type: str) -> str:
    return "SPAN_KIND_CLIENT" if span_type in {"generation", "response"} else "SPAN_KIND_INTERNAL"


def _span_name(span_type: str, data: Mapping[str, Any]) -> str:
    if data.get("name"):
        return f"{span_type}.{data['name']}"
    if data.get("model"):
        return f"{span_type}.{data['model']}"
    return span_type


def _expand_messages(prefix: str, messages: Iterable[Mapping[str, Any]]) -> dict[str, Any]:
    attrs: dict[str, Any] = {}
    for index, message in enumerate(messages or []):
        if not isinstance(message, Mapping):
            continue
        role = message.get("role")
        content = message.get("content")
        if role is not None:
            attrs[f"{prefix}.{index}.message.role"] = role
        if isinstance(content, str):
            attrs[f"{prefix}.{index}.message.content"] = content
        elif content is not None:
            attrs[f"{prefix}.{index}.message.content"] = _json(content)
        for tool_index, tool_call in enumerate(message.get("tool_calls") or []):
            function = (tool_call or {}).get("function") or {}
            attrs[f"{prefix}.{index}.message.tool_calls.{tool_index}.tool_call.id"] = (
                tool_call or {}
            ).get("id")
            attrs[
                f"{prefix}.{index}.message.tool_calls.{tool_index}.tool_call.function.name"
            ] = function.get("name")
            attrs[
                f"{prefix}.{index}.message.tool_calls.{tool_index}.tool_call.function.arguments"
            ] = function.get("arguments")
        if message.get("tool_call_id"):
            attrs[f"{prefix}.{index}.message.tool_call_id"] = message["tool_call_id"]
        if message.get("name"):
            attrs[f"{prefix}.{index}.message.name"] = message["name"]
    return {key: value for key, value in attrs.items() if value is not None}


def _json(value: Any) -> str | None:
    if value is None:
        return None
    return json.dumps(value, default=str, separators=(",", ":"))


def _json_safe(value: Any) -> bool:
    return isinstance(value, (str, int, float, bool)) or value is None


def _int(value: Any) -> int | None:
    if value is None:
        return None
    try:
        return int(value)
    except (TypeError, ValueError):
        return None


def _drop_none(values: Mapping[str, Any]) -> dict[str, Any]:
    return {key: value for key, value in values.items() if value is not None}


def _sdk_version() -> str:
    try:
        return version("openai-agents")
    except Exception:
        return "unknown"
运行 SDK 智能体
run_sdk_agent() 直接调用 Agents SDK 运行器,同时处理每次追踪运行周围的重复设置:挂载数据、附加追踪、执行智能体以及收集输出工件。
async def run_sdk_agent(
    dataset_dir: Path,
    output_dir: Path,
    question: str,
    model: str,
    agent_config: AgentConfig,
    trace_id: str | None = None,
    trace_metadata: dict[str, Any] | None = None,
    halo_trace_path: str | Path | None = None,
    halo_project_id: str = "financial_diligence_analyst_optimization_context",
) -> str:
    from agents import ModelSettings as SDKModelSettings
    from agents import Runner, custom_span, flush_traces, trace
    from agents.run import RunConfig
    from agents.sandbox import Manifest, SandboxAgent, SandboxRunConfig
    from agents.sandbox.entries import Dir, LocalDir
    from agents.sandbox.sandboxes.unix_local import UnixLocalSandboxClient
    from openai.types.shared import Reasoning

    output_dir.mkdir(parents=True, exist_ok=True)
    with staged_dataset_mount(dataset_dir) as staged_dataset_dir:
        write_runtime_manifest(staged_dataset_dir)
        reasoning = Reasoning(effort=agent_config.model_settings.reasoning_effort)
        agent = SandboxAgent(
            name="Synthetic dataroom diligence analyst",
            model=model,
            model_settings=SDKModelSettings(reasoning=reasoning),
            instructions=agent_config.build_instructions(),
            default_manifest=Manifest(
                entries={
                    "data": LocalDir(src=staged_dataset_dir),
                    "outputs": Dir(),
                }
            ),
        )
        client = UnixLocalSandboxClient()
        session = None
        halo_processor = None
        if halo_trace_path is not None:
            halo_processor = setup_halo_tracing(
                halo_trace_path,
                project_id=halo_project_id,
                service_version=agent_config.version,
                deployment_environment="notebook" if trace_metadata else None,
                extra_resource_attributes={
                    "agent.config.version": agent_config.version,
                    "agent.config.path": str(agent_config.path),
                },
            )
        trace_context = (
            trace(
                workflow_name="Synthetic dataroom diligence",
                trace_id=trace_id,
                metadata=trace_metadata,
            )
            if trace_id
            else None
        )
        if trace_context is not None:
            trace_context.__enter__()
        try:
            with custom_span(
                "sandbox_workspace",
                {
                    "tool.name": "sandbox_workspace",
                    "tool.input": {
                        "mounted": "data",
                        "writable": "outputs",
                        "dataset_dir": str(dataset_dir),
                        "staged_dataset_dir": str(staged_dataset_dir),
                        "agent_config": str(agent_config.path),
                        "agent_config_version": agent_config.version,
                    },
                },
                disabled=trace_context is None,
            ):
                with custom_span(
                    "agent_config",
                    {
                        "tool.name": "agent_config",
                        "tool.input": {
                            "version": agent_config.version,
                            "required_artifacts": agent_config.required_artifacts,
                        },
                    },
                    disabled=trace_context is None,
                ):
                    pass
                session = await client.create(manifest=agent.default_manifest)
            async with session:
                result = await Runner.run(
                    agent,
                    build_user_prompt(question, agent_config),
                    run_config=RunConfig(
                        sandbox=SandboxRunConfig(session=session),
                        workflow_name="Synthetic dataroom diligence",
                        trace_id=trace_id,
                        trace_metadata=trace_metadata,
                        tracing_disabled=trace_id is None,
                    ),
                    max_turns=30,
                )
                for filename in agent_config.required_artifacts:
                    try:
                        with custom_span(
                            "artifact_write",
                            {
                                "tool.name": "artifact_write",
                                "tool.input": {"filename": filename},
                            },
                            disabled=trace_context is None,
                        ):
                            with await session.read(Path("outputs") / filename) as handle:
                                (output_dir / filename).write_bytes(handle.read())
                    except Exception:
                        continue
                return str(result.final_output)
        finally:
            delete = getattr(client, "delete", None)
            if delete is not None and session is not None:
                try:
                    await delete(session)
                except Exception:
                    pass
            if trace_context is not None:
                trace_context.__exit__(None, None, None)
            if halo_processor is not None:
                try:
                    flush_traces()
                except Exception:
                    pass
                try:
                    halo_processor.shutdown()
                except Exception:
                    pass


@contextmanager
def staged_dataset_mount(dataset_dir: Path) -> Iterator[Path]:
    """Prepare a writable SDK mount copy without mutating the source dataroom."""
    with tempfile.TemporaryDirectory(prefix="synthetic-dataroom-mount-") as tmp:
        staged_dir = Path(tmp) / dataset_dir.name
        shutil.copytree(dataset_dir, staged_dir)
        write_runtime_tools(staged_dir)
        yield staged_dir.resolve()


def write_runtime_manifest(dataset_dir: Path) -> None:
    manifest = {
        "runtime_scope": "sdk_agent_visible_dataroom",
        "files": sorted(
            str(path.relative_to(dataset_dir))
            for path in dataset_dir.rglob("*")
            if path.is_file() and path.name != "manifest.json"
        ),
    }
    (dataset_dir / "manifest.json").write_text(
        json.dumps(manifest, indent=2) + "\n",
        encoding="utf-8",
    )
步骤 3. 生成追踪运行
这些问题有意多样化,以便评估套件覆盖智能体可能出错的多种方式。笔记本默认运行五次追踪,以保持实时路径的实用性,同时仍覆盖几种不同的行为。如果您希望以后获得更广泛的覆盖,更大的问题库仍然可用。
每次运行都使用异步 Agents SDK 路径,并写入真实追踪以及所需的工件。
QUESTION_BANK = [
    "What do runway and burn tell us about near-term financing risk?",
    "How strong is revenue quality, and which ARR figure should we rely on?",
    "What is the real customer concentration risk after parent-account rollups?",
    "What legal exposure should an acquirer investigate first?",
    "How ready is the company for enterprise security review?",
    "Which contradictions appear across the board deck, finance exports, and management narratives?",
    "What unsupported metrics should we refuse to infer from the dataroom?",
    "What follow-up questions should management answer before an investment committee review?",
    "What are the top three diligence risks, ranked by severity?",
    "Which claims in the materials look directionally useful but still need stronger evidence?",
]

# Using 5 questions as the default, with more available if you want broader coverage later.

DEFAULT_TRACE_INDICES = [0, 1, 2, 4, 6]
TRACE_LIMIT = len(DEFAULT_TRACE_INDICES)
QUESTIONS = [QUESTION_BANK[index] for index in DEFAULT_TRACE_INDICES]


@dataclass
class TraceRecord:
    trace_id: str
    sdk_trace_id: str
    trace_label: str
    question: str
    answer: str
    output_dir: str
    mode: str


def sdk_trace_id(label: str) -> str:
    # Agents SDK trace uploads expect ids shaped like `trace_<hex>`.
    return f"trace_{hashlib.sha256(label.encode('utf-8')).hexdigest()[:32]}"


def exported_trace_id(label: str) -> str:
    # The local HALO exporter strips the SDK `trace_` prefix before writing JSONL.
    return sdk_trace_id(label).removeprefix("trace_")


async def generate_traces(dataset: Path, questions: list[str]) -> list[TraceRecord]:
    traces: list[TraceRecord] = []
    for index, question in enumerate(questions, start=1):
        label = f"trace-{index:02d}"
        print(f"Running {label}/{len(questions):02d}: {question}")
        output_dir = TRACE_DIR / f"trace_{index:02d}"
        output_dir.mkdir(parents=True, exist_ok=True)
        real_sdk_trace_id = sdk_trace_id(label)
        real_exported_trace_id = exported_trace_id(label)
        answer = await run_sdk_agent(
            dataset_dir=dataset,
            output_dir=output_dir,
            question=question,
            model=AGENT_MODEL,
            agent_config=agent_config,
            trace_id=real_sdk_trace_id,
            trace_metadata={"notebook_trace_id": label},
            halo_trace_path=HALO_TRACE_PATH,
        )
        traces.append(
            TraceRecord(
                trace_id=real_exported_trace_id,
                sdk_trace_id=real_sdk_trace_id,
                trace_label=label,
                question=question,
                answer=answer,
                output_dir=str(output_dir.relative_to(PROJECT_ROOT)),
                mode="sdk",
            )
        )
    return traces


trace_generation_started = time.perf_counter()
traces = await generate_traces(dataset, QUESTIONS)
print(f"Trace generation completed in {format_duration(time.perf_counter() - trace_generation_started)}")
assert len(traces) == TRACE_LIMIT

for trace in traces:
    print(f"{trace.trace_label}: {trace.question}")
    print(textwrap.shorten(trace.answer.replace("\n", " "), width=180, placeholder="..."))
    print()
检查代理产物
每次追踪的运行都会写入测试平台所需的完整产物集。下面的第一次运行显示了代理生成的文件,以便你可以一起检查答案、证据和未解决的问题。
def show_trace_artifacts(trace: TraceRecord) -> None:
    output_dir = PROJECT_ROOT / trace.output_dir
    for artifact in agent_config.required_artifacts:
        path = output_dir / artifact
        language = {
            ".md": "markdown",
            ".json": "json",
            ".csv": "csv",
        }.get(path.suffix, "text")
        display(Markdown(f"### `{artifact}`\n```{language}\n{path.read_text(encoding='utf-8').rstrip()}\n```"))


show_trace_artifacts(traces[0])
步骤 4. 生成示例人工反馈和模型见解
本节模拟人类专家在代理运行后审查轨迹。在真实的尽职调查工作流程中,这可能是财务负责人或其他案例专家,他们知道哪些细节对决策至关重要。在此示例中,审查者指出,父账户汇总比法人实体集中度更重要,未经验证的管理层 NRR 估计不应成为官方指标,并且当证据仅支持 Type I 时,“SOC 2 完成”过于模糊。
模型生成的见解保持独立。在完全自动化的路径中,LLM 审查相同的轨迹并提出重复出现的问题或缺失的行为。额外的检查提高了覆盖率,而主题专家审查则基于工作本身增加了领域判断。
def feedback_item(
    trace: TraceRecord,
    summary: str,
    required: list[str],
    prohibited: list[str],
    theme: str,
) -> dict[str, Any]:
    return {
        "feedback_id": f"human-{trace.trace_label}",
        "trace_id": trace.trace_id,
        "trace_label": trace.trace_label,
        "question": trace.question,
        "source_type": "human_feedback",
        "theme": theme,
        "summary": summary,
        "required_observations": required,
        "prohibited_claims": prohibited,
    }


def generate_mock_human_feedback(traces: list[TraceRecord]) -> list[dict[str, Any]]:
    specs_by_question = {
        "What do runway and burn tell us about near-term financing risk?": (
            "State both the 11-month runway and rising burn as financing risk, not just a generic red flag.",
            ["Name the 11-month runway", "Tie burn to near-term financing pressure"],
            ["Do not imply the company has more than 12 months of runway"],
            "financial_risk",
        ),
        "How strong is revenue quality, and which ARR figure should we rely on?": (
            "Use the controlled ARR bridge as the reliable figure and preserve the board-versus-finance contradiction.",
            ["Prefer finance ARR over board ARR", "Preserve the ARR contradiction"],
            ["Do not silently reconcile the ARR gap"],
            "revenue_quality",
        ),
        "What is the real customer concentration risk after parent-account rollups?": (
            "Roll concentration up to Northstar Holdings. Legal-entity framing understates the real dependency.",
            ["Mention parent-account concentration", "Use account_hierarchy.csv"],
            ["Do not stop at legal-entity concentration"],
            "customer_concentration",
        ),
        "How ready is the company for enterprise security review?": (
            "Be exact about certification status: Type I is complete; Type II is still in progress.",
            ["Distinguish Type I from Type II", "Treat sales FAQ as weaker evidence"],
            ["Do not say SOC 2 is simply complete"],
            "security_readiness",
        ),
        "What unsupported metrics should we refuse to infer from the dataroom?": (
            "Refuse official NRR and CAC payback when the dataroom does not support them.",
            ["Mark official NRR unsupported", "Mark CAC payback unsupported"],
            ["Do not promote the management NRR estimate into an official metric"],
            "unsupported_metrics",
        ),
    }
    return [feedback_item(trace, *specs_by_question[trace.question]) for trace in traces]


def extract_json(text: str) -> Any:
    text = text.strip()
    fenced = re.search(r"```(?:json)?\s*(.*?)```", text, flags=re.DOTALL)
    candidate = fenced.group(1).strip() if fenced else text
    return json.loads(candidate)


def generate_llm_feedback(traces: list[TraceRecord]) -> list[dict[str, Any]]:
    payload = [asdict(trace) for trace in traces]
    response = client.responses.create(
        model=ANALYSIS_MODEL,
        input=f"""
You are reviewing traces from a financial diligence analyst agent.
Return JSON only: a list of objects with keys `insight_id`, `trace_id`, `question`, `source_type`, and `observations`.
Use `source_type` = `llm_insight`.
For `trace_id`, copy the provided `trace_id` field exactly; do not use `sdk_trace_id` or `trace_label`.
For each trace, identify concise recurring-behavior observations that could help generate evals later.
Do not restate the whole answer. Do not invent unavailable evidence.

Traces:
{json.dumps(payload, indent=2)}
""".strip(),
    )
    parsed = extract_json(response.output_text)
    if not isinstance(parsed, list):
        raise ValueError("Expected a JSON list of LLM insights.")
    trace_labels = {trace.trace_id: trace.trace_label for trace in traces}
    for item in parsed:
        try:
            item["trace_label"] = trace_labels[item["trace_id"]]
        except KeyError as exc:
            raise ValueError(f"Unknown trace_id in LLM feedback: {item['trace_id']}") from exc
    return parsed


feedback_started = time.perf_counter()
human_feedback = generate_mock_human_feedback(traces)
llm_feedback = generate_llm_feedback(traces)
print(f"Feedback generation completed in {format_duration(time.perf_counter() - feedback_started)}")
assert len(human_feedback) == TRACE_LIMIT
assert len(llm_feedback) == TRACE_LIMIT

print("Human feedback items:", len(human_feedback))
print("LLM insight items:", len(llm_feedback))
print("\nExample human feedback:")
print(json.dumps(human_feedback[0], indent=2))
print("\nExample LLM insight:")
print(json.dumps(llm_feedback[0], indent=2))
步骤 5:从追踪和反馈生成 Promptfoo 评估
评估套件由 LLM 根据目前收集到的证据(追踪行为、人工反馈和模型生成的观察)动态生成。这会将评论转化为测试,供后续的 harness 修订版再次运行。
Promptfoo 是一个开源 CLI 和库,用于评估和红队测试 LLM 应用。在本笔记本中,生成的行为成为 Promptfoo 测试用例:每个用例可以结合字面断言和 LLM 评分器,因此同一个门控可以同时检查精确要求和语义审查者意图。
评估是投入领域专家和开发人员手动工作的好地方。全自动流程可以快速提出有用的评估,但在评估成为长期测试套件的一部分之前,人们仍应检查评估是否准确、具有代表性,并且衡量的是真正重要的行为。
def generate_feedback_derived_evals(
    traces: list[TraceRecord],
    human_feedback: list[dict[str, Any]],
    llm_feedback: list[dict[str, Any]],
) -> list[dict[str, Any]]:
    min_eval_count = min(5, max(2, len(traces)))
    max_eval_count = min(7, max(min_eval_count, len(traces) + 2))
    response = client.responses.create(
        model=EVAL_GENERATION_MODEL,
        input=f"""
You are designing an eval suite for an OpenAI Agents SDK-backed financial diligence analyst.
Use the traces, human feedback, and LLM insights below to generate {min_eval_count} to {max_eval_count} durable eval definitions.
Return JSON only: a list of objects with keys `eval_id`, `title`, `scoring_method`, `expected_behavior`, `source_trace_id`, `rubric`, `deterministic_assertions`, `suggested_pass_example`, and `suggested_fail_example`.
`scoring_method` must be one of `deterministic`, `llm_judge`, or `hybrid`.
`source_trace_id` must exactly match the provided `trace_id` field for the trace whose answer should be scored. Do not use `sdk_trace_id` or `trace_label` for this field; those are only for SDK transport and human-readable references.
`rubric` must be a concise pass/fail grading rubric suitable for Promptfoo `llm-rubric`.
`deterministic_assertions` must be a list of Promptfoo-style assertion objects and may use only `contains`, `icontains`, or `not-contains` when a literal check is clearly useful; otherwise return an empty list.
Prefer reusable behaviors over one-off trace restatements.

Traces:
{json.dumps([asdict(trace) for trace in traces], indent=2)}

Human feedback:
{json.dumps(human_feedback, indent=2)}

LLM insights:
{json.dumps(llm_feedback, indent=2)}
""".strip(),
    )
    parsed = extract_json(response.output_text)
    if not isinstance(parsed, list):
        raise ValueError("Expected a JSON list of eval definitions.")
    trace_labels = {trace.trace_id: trace.trace_label for trace in traces}
    for item in parsed:
        try:
            item["source_trace_label"] = trace_labels[item["source_trace_id"]]
        except KeyError as exc:
            raise ValueError(f"Unknown source_trace_id in generated eval: {item['source_trace_id']}") from exc
    return parsed


eval_generation_started = time.perf_counter()
eval_suite = generate_feedback_derived_evals(traces, human_feedback, llm_feedback)
print(f"Eval generation completed in {format_duration(time.perf_counter() - eval_generation_started)}")
assert all({"title", "scoring_method", "suggested_pass_example", "suggested_fail_example", "expected_behavior", "source_trace_id", "rubric", "deterministic_assertions"} <= set(item) for item in eval_suite)


def markdown_table(rows: list[dict[str, Any]], columns: list[str]) -> str:
    header = "| " + " | ".join(columns) + " |"
    divider = "| " + " | ".join(["---"] * len(columns)) + " |"
    body = ["| " + " | ".join(str(row[column]) for column in columns) + " |" for row in rows]
    return "\n".join([header, divider, *body])


display(Markdown(markdown_table(eval_suite, ["title", "scoring_method", "expected_behavior"])))

for item in eval_suite:
    print(f"\n{item['title']}")
    print(" pass:", item["suggested_pass_example"])
    print(" fail:", item["suggested_fail_example"])
步骤 6:使用 Promptfoo 验证当前测试框架
Promptfoo 会根据当前的追踪输出运行生成的测试。这为循环提供了一个快照,显示测试框架在哪些方面已经表现良好,以及哪些预期仍然失败。Promptfoo 适合这个角色,因为它可以将对字面要求的确定性检查与用于语义质量的 llm-rubric 评判器结合起来。
在本笔记本中,Promptfoo 门控会对现有的追踪输出进行评分。要验证未来的测试框架修订版,请将追踪输出提供程序替换为运行候选代理的提供程序。这些 Promptfoo 结果将成为下面传递给 HALO 的优化输入的一部分。即使评估生成是自动化的,人类仍然可以在让弱评估引导重复优化之前加强它们。
构建 Promptfoo 测试框架
该提供程序将现有的追踪输出返回给 Promptfoo,而测试构建器则将生成的评估定义转换为可运行的 Promptfoo 测试用例。
PROMPTFOO_PROVIDER = r'''from __future__ import annotations

import json
from pathlib import Path


def call_api(prompt: str, options: dict, context: dict) -> dict:
    config = options.get("config", {})
    trace_outputs = json.loads(Path(config["trace_outputs_path"]).read_text(encoding="utf-8"))
    trace_id = (context.get("vars") or {}).get("trace_id")
    trace = trace_outputs[trace_id]
    return {
        "output": trace["answer"],
        "metadata": {
            "trace_id": trace_id,
            "question": trace["question"],
        },
    }
'''


def trace_for_eval(item: dict[str, Any], traces: list[TraceRecord]) -> TraceRecord:
    trace_by_id = {trace.trace_id: trace for trace in traces}
    try:
        return trace_by_id[item["source_trace_id"]]
    except KeyError as exc:
        raise ValueError(f"Unknown source_trace_id in generated eval: {item['source_trace_id']}") from exc

def promptfoo_test_from_eval(item: dict[str, Any], trace: TraceRecord) -> dict[str, Any]:
    assertions = [
        assertion
        for assertion in item.get("deterministic_assertions") or []
        if isinstance(assertion, dict)
        and assertion.get("type") in {"contains", "icontains", "not-contains"}
        and assertion.get("value")
    ]
    assertions.append({
        "type": "llm-rubric",
        "provider": f"openai:{JUDGE_MODEL}",
        "threshold": 0.8,
        "value": item["rubric"],
    })
    return {
        "description": item["title"],
        "vars": {
            "question": trace.question,
            "trace_id": trace.trace_id,
            "trace_label": trace.trace_label,
        },
        "metadata": {
            "eval_id": item["eval_id"],
            "scoring_method": item["scoring_method"],
        },
        "assert": assertions,
    }


def write_promptfoo_artifacts(eval_suite: list[dict[str, Any]], traces: list[TraceRecord]) -> dict[str, Path]:
    promptfoo_dir = ARTIFACT_DIR / "promptfoo"
    promptfoo_dir.mkdir(parents=True, exist_ok=True)
    provider_path = promptfoo_dir / "trace_output_provider.py"
    trace_outputs_path = promptfoo_dir / "trace_outputs.json"
    config_path = promptfoo_dir / "promptfooconfig.yaml"
    output_path = promptfoo_dir / "promptfoo_results.json"

    provider_path.write_text(PROMPTFOO_PROVIDER, encoding="utf-8")
    trace_outputs_path.write_text(
        json.dumps({trace.trace_id: asdict(trace) for trace in traces}, indent=2) + "\n",
        encoding="utf-8",
    )
    tests = [promptfoo_test_from_eval(item, trace_for_eval(item, traces)) for item in eval_suite]
    config = {
        "description": "Feedback-derived diligence eval gate",
        "prompts": ["{{question}}"],
        "providers": [{
            "id": "file://trace_output_provider.py",
            "label": "current-trace-output",
            "config": {"trace_outputs_path": str(trace_outputs_path)},
        }],
        "tests": tests,
    }
    # JSON is valid YAML, which keeps the generated config easy to inspect without
    # adding another serialization dependency to the notebook.
    config_path.write_text(json.dumps(config, indent=2) + "\n", encoding="utf-8")
    return {
        "dir": promptfoo_dir,
        "provider": provider_path,
        "trace_outputs": trace_outputs_path,
        "config": config_path,
        "output": output_path,
    }


def promptfoo_summary(path: Path) -> dict[str, Any]:
    data = json.loads(path.read_text(encoding="utf-8"))
    results = (data.get("results") or {}).get("outputs") or (data.get("results") or {}).get("results") or []
    rows = []
    for result in results:
        grading = result.get("gradingResult") or {}
        components = grading.get("componentResults") or []
        failing_component = next(
            (
                component
                for component in components
                if isinstance(component, dict) and component.get("pass") is False
            ),
            None,
        )
        reason = str(grading.get("reason") or "")
        if not reason and failing_component:
            reason = str(failing_component.get("reason") or "")
        if not reason and components and isinstance(components[0], dict):
            reason = str(components[0].get("reason") or "")
        test_case = result.get("testCase") or {}
        test_vars = test_case.get("vars") or {}
        rows.append({
            "eval_id": (test_case.get("metadata") or {}).get("eval_id"),
            "title": test_case.get("description") or "Untitled",
            "trace_id": test_vars.get("trace_id"),
            "trace_label": test_vars.get("trace_label"),
            "passed": bool(result.get("success")),
            "score": result.get("score"),
            "explanation": reason,
        })
    return {
        "backend": "promptfoo",
        "total": len(rows),
        "passed": sum(row["passed"] for row in rows),
        "failed": sum(not row["passed"] for row in rows),
        "rows": rows,
    }
运行 Promptfoo 门禁
执行生成的测试套件并总结当前测试工具的结果。
def run_promptfoo_feedback_eval_gate(eval_suite: list[dict[str, Any]], traces: list[TraceRecord]) -> dict[str, Any]:
    artifacts = write_promptfoo_artifacts(eval_suite, traces)
    command = [
        "npx",
        "--yes",
        f"promptfoo@{PROMPTFOO_VERSION}",
        "eval",
        "--no-cache",
        "--no-table",
        "-c",
        str(artifacts["config"]),
        "-o",
        str(artifacts["output"]),
    ]
    env = os.environ.copy()
    env["PROMPTFOO_PYTHON"] = sys.executable
    env["PROMPTFOO_CONFIG_DIR"] = str(artifacts["dir"] / ".promptfoo")
    env["PROMPTFOO_DISABLE_WAL_MODE"] = "true"
    process = subprocess.run(
        command,
        cwd=artifacts["dir"],
        env=env,
        text=True,
        stdout=subprocess.PIPE,
        stderr=subprocess.STDOUT,
        check=False,
    )
    if not artifacts["output"].exists():
        raise RuntimeError(f"Promptfoo did not write results. Output:\n{process.stdout[-4000:]}")
    summary = promptfoo_summary(artifacts["output"])
    summary["command"] = command
    summary["returncode"] = process.returncode
    summary["result_path"] = str(artifacts["output"].relative_to(PROJECT_ROOT))
    summary["log_tail"] = process.stdout[-4000:]
    return summary


promptfoo_started = time.perf_counter()
gate_result = run_promptfoo_feedback_eval_gate(eval_suite, traces)
print(f"Promptfoo gate completed in {format_duration(time.perf_counter() - promptfoo_started)}")
display(Markdown(markdown_table(gate_result["rows"], ["title", "trace_label", "passed", "score", "explanation"])))
print({key: gate_result[key] for key in ["backend", "total", "passed", "failed", "result_path"]})
第7步:运行HALO并编写交接文档
HALO,即分层代理循环优化(Hierarchical Agent Loop Optimization),是一种方法论和Python包,用于从执行轨迹中改进代理框架。HALO仓库描述了一个循环:收集轨迹,分析反复出现的框架级失败,将生成的报告交给编码代理,并在框架更改后重复此过程。
此时,循环将累积的证据转化为建议的框架更改。HALO会结合代理轨迹、人工反馈、模型反馈、生成的评估和Promptfoo结果来审查当前框架。然后,它会生成一组按优先级排序的更改,供下一轮实现使用。
HALO在此处的价值在于,它能同时推理整个循环。它可以将人工判断与运行时行为和评估结果相结合,然后将结果打包为交接文档,供Codex用于实现改进框架的代码更改。
收集 HALO 输入
构建一个上下文对象,将当前的测试框架、追踪、反馈、评估和门控结果整合在一起。
from datetime import datetime, timezone


def serialize_agent_config(config: AgentConfig) -> dict[str, Any]:
    return {
        "version": config.version,
        "system_prompt": config.system_prompt,
        "model_settings": asdict(config.model_settings),
        "tool_policy": config.tool_policy,
        "eval_metadata": config.eval_metadata,
    }


def build_halo_context(
    traces: list[TraceRecord],
    human_feedback: list[dict[str, Any]],
    llm_feedback: list[dict[str, Any]],
    eval_suite: list[dict[str, Any]],
    gate_result: dict[str, Any],
    agent_config: AgentConfig,
) -> dict[str, Any]:
    return {
        "traces": [asdict(trace) for trace in traces],
        "human_feedback": human_feedback,
        "llm_feedback": llm_feedback,
        "eval_suite": eval_suite,
        "gate_result": gate_result,
        "agent_config": serialize_agent_config(agent_config),
    }


def synthetic_trace_id(value: str) -> str:
    return hashlib.sha256(f"halo-context-{value}".encode("utf-8")).hexdigest()[:32]


def synthetic_span_id(value: str) -> str:
    return hashlib.sha256(value.encode("utf-8")).hexdigest()[:16]


def synthetic_span(*, trace_id: str, span_id: str, name: str, observation_kind: str, attributes: dict[str, Any]) -> dict[str, Any]:
    now = datetime.now(timezone.utc).strftime("%Y-%m-%dT%H:%M:%S.%f000Z")
    return {
        "trace_id": trace_id,
        "span_id": span_id,
        "parent_span_id": "",
        "trace_state": "",
        "name": name,
        "kind": "SPAN_KIND_INTERNAL",
        "start_time": now,
        "end_time": now,
        "status": {"code": "STATUS_CODE_OK", "message": ""},
        "resource": {"attributes": {"service.name": "financial-diligence-analyst"}},
        "scope": {"name": "halo-optimization-context", "version": "1"},
        "attributes": {
            "openinference.span.kind": observation_kind,
            "inference.export.schema_version": 1,
            "inference.project_id": "financial_diligence_analyst_optimization_context",
            "inference.observation_kind": observation_kind,
            **attributes,
        },
    }


def halo_input_summary(context: dict[str, Any]) -> str:
    rows = [
        ("Current harness config", 1, "global config span", "system prompt, model settings, tool policy, eval metadata"),
        ("SDK execution traces", len(context["traces"]), "original runtime traces", "agent steps, tool calls, outputs"),
        ("Human feedback", len(context["human_feedback"]), "appended to the source trace", "reviewer summary, required observations, prohibited claims"),
        ("LLM feedback", len(context["llm_feedback"]), "appended to the source trace", "model-generated observations"),
        ("Generated eval definitions", len(context["eval_suite"]), "appended to the source trace", "expected behavior, rubric, pass/fail examples"),
        ("Promptfoo row results", len(context["gate_result"]["rows"]), "appended to the source trace", "pass/fail outcome and explanation"),
        ("Promptfoo gate summary", 1, "global summary span", "suite totals across all evals"),
    ]
    lines = [
        "### HALO input summary",
        "",
        "| Input signal | Count | Where it lives | What is included |",
        "| --- | ---: | --- | --- |",
    ]
    lines.extend(f"| {name} | {count} | {location} | {included} |" for name, count, location, included in rows)
    return "\n".join(lines)
将反馈、生成的评估和评估结果附加到追踪中
编写 HALO 将检查的组合追踪文件。人工反馈、LLM 反馈、生成的评估定义以及行级 Promptfoo 结果都会附加到匹配的运行时追踪中。整体门控摘要保持全局性,因为它描述的是整个测试套件。
def write_halo_optimization_context(context: dict[str, Any]) -> Path:
    context_path = ARTIFACT_DIR / "halo_optimization_context.jsonl"
    lines = HALO_TRACE_PATH.read_text(encoding="utf-8").splitlines() if HALO_TRACE_PATH.exists() else []
    lines.append(json.dumps(synthetic_span(
        trace_id=synthetic_trace_id("current-harness-config"),
        span_id=synthetic_span_id("current-harness-config"),
        name="harness.config",
        observation_kind="HARNESS_CONFIG",
        attributes={
            "harness.version": context["agent_config"]["version"],
            "harness.system_prompt": context["agent_config"]["system_prompt"],
            "harness.model_settings": json.dumps(context["agent_config"]["model_settings"]),
            "harness.tool_policy": json.dumps(context["agent_config"]["tool_policy"]),
            "harness.eval_metadata": json.dumps(context["agent_config"]["eval_metadata"]),
            "optimizer.signal_source": "harness_config",
        },
    )))
    for index, item in enumerate(context["human_feedback"]):
        lines.append(json.dumps(synthetic_span(
            trace_id=item["trace_id"],
            span_id=synthetic_span_id(f"human-feedback-{index}"),
            name="human_feedback.comment",
            observation_kind="HUMAN_FEEDBACK",
            attributes={
                "feedback.id": item["feedback_id"],
                "feedback.trace_id": item["trace_id"],
                "feedback.trace_label": item["trace_label"],
                "feedback.question": item["question"],
                "feedback.summary": item["summary"],
                "feedback.required_observations": json.dumps(item["required_observations"]),
                "feedback.prohibited_claims": json.dumps(item["prohibited_claims"]),
                "optimizer.signal_source": "human_feedback",
            },
        )))
    for index, item in enumerate(context["llm_feedback"]):
        lines.append(json.dumps(synthetic_span(
            trace_id=item["trace_id"],
            span_id=synthetic_span_id(f"llm-insight-{index}"),
            name="llm_feedback.insight",
            observation_kind="LLM_FEEDBACK",
            attributes={
                "llm_feedback.id": item["insight_id"],
                "llm_feedback.trace_id": item["trace_id"],
                "llm_feedback.trace_label": item["trace_label"],
                "llm_feedback.question": item["question"],
                "llm_feedback.observations": json.dumps(item["observations"]),
                "optimizer.signal_source": "llm_feedback",
            },
        )))
    for index, item in enumerate(context["eval_suite"]):
        lines.append(json.dumps(synthetic_span(
            trace_id=item["source_trace_id"],
            span_id=synthetic_span_id(f"generated-eval-{index}"),
            name="generated_eval.definition",
            observation_kind="EVAL",
            attributes={
                "eval.id": item["eval_id"],
                "eval.trace_id": item["source_trace_id"],
                "eval.trace_label": item["source_trace_label"],
                "eval.title": item["title"],
                "eval.method": item["scoring_method"],
                "eval.expected_behavior": item["expected_behavior"],
                "eval.pass_example": item["suggested_pass_example"],
                "eval.fail_example": item["suggested_fail_example"],
                "optimizer.signal_source": "generated_eval",
            },
        )))
    lines.append(json.dumps(synthetic_span(
        trace_id=synthetic_trace_id("eval-gate-summary"),
        span_id=synthetic_span_id("eval-gate-summary"),
        name="eval_gate.summary",
        observation_kind="EVAL_RESULT",
        attributes={
            "eval_gate.total": context["gate_result"]["total"],
            "eval_gate.passed": context["gate_result"]["passed"],
            "eval_gate.failed": context["gate_result"]["failed"],
            "optimizer.signal_source": "eval_gate",
        },
    )))
    for index, item in enumerate(context["gate_result"]["rows"]):
        lines.append(json.dumps(synthetic_span(
            trace_id=item["trace_id"],
            span_id=synthetic_span_id(f"eval-gate-row-{index}"),
            name="eval_gate.result",
            observation_kind="EVAL_RESULT",
            attributes={
                "eval.id": item["eval_id"],
                "eval.title": item["title"],
                "eval.trace_id": item["trace_id"],
                "eval.trace_label": item["trace_label"],
                "eval.passed": item["passed"],
                "eval.explanation": item["explanation"],
                "optimizer.signal_source": "eval_gate",
            },
        )))
    context_path.write_text("\n".join(lines).rstrip() + "\n", encoding="utf-8")
    return context_path
定义 HALO 输出提示词
此提示词告诉 HALO 应生成何种报告,包括 Codex 在最终交接文件中应接收的部分。你可以根据公司的流程、审查流程或用例对其进行自定义。
def render_halo_prompt() -> str:
    return """
Analyze the financial diligence analyst optimization context as the central source of truth.
The JSONL contains the current harness configuration, agent execution traces, human feedback, LLM insights, generated eval definitions, and eval-gate results.
Treat human feedback as first-class evidence.
Before recommending a change, compare the evidence against the current harness config and distinguish:
- a requirement that is missing from the harness,
- a requirement already present but not reliably followed in execution, and
- an implementation or observability defect.

Write an implementation-first Codex handoff in this exact top-level order:
1. `## Executive summary`
2. `## Top 3 changes to implement first`
3. `## Ranked recommendation table`
4. `## Supporting diagnosis and evidence`
5. `## Detailed recommendations`
6. `## Insights by feedback source`
7. `## Machine-readable summary`

Section requirements:
- `## Executive summary`: briefly state what the current harness already does well, what the highest-value remaining gaps are, and whether the current eval gate passed.
- `## Top 3 changes to implement first`: list the three most valuable implementation moves with concise rationale.
- `## Ranked recommendation table`: include rank, recommendation, impact, confidence, implementation effort, evidence, and validation.
- `## Supporting diagnosis and evidence`: include recurring harness-level failure modes, classify each against the current harness as missing requirement vs already-present-but-not-reliably-followed vs implementation/observability defect, and state the evidence source for each.
- `## Detailed recommendations`: use these exact subsection headings in this order and do not use the word "owner" in them:
  - `### Behavior contract`
    - `#### Prompt`
    - `#### Skills`
  - `### Runtime implementation`
    - `#### Tools`
    - `#### Control flow`
    - `#### Routing`
  - `### Output contract`
    - `#### Artifact schema`
  - `### Observability and evals`
    - `#### Observability`
    - `#### Evals`
- `## Insights by feedback source`: summarize what came from traces, human feedback, LLM feedback, generated evals, eval-gate results, and harness config.
- `## Machine-readable summary`: include one fenced JSON block with `top_priorities`.

Do not add extra top-level sections outside that order.
""".strip()
运行 HALO 并格式化报告
HALO 接收五个 SDK 执行轨迹,外加两个合成的全局轨迹:一个记录当前测试框架配置,另一个记录 Promptfoo 门控摘要。这就是为什么它的轨迹数量高于之前创建的五次代理运行。
生成完整的优化报告,保存交接工件,并在笔记本中显示最高优先级的建议。
async def run_halo_optimization(context_path: Path) -> str:
    from agents import set_trace_processors
    from engine.agents.agent_config import AgentConfig as HaloAgentConfig
    from engine.engine_config import EngineConfig
    from engine.main import stream_engine_async
    from engine.sandbox.sandbox import Sandbox
    from engine.model_config import ModelConfig
    from engine.models.engine_output import AgentOutputItem, AgentTextDelta
    from engine.models.messages import AgentMessage

    # HALO's current CLI wrapper sets compaction temperature to 0.0, which is not
    # accepted by GPT-5-class models. Use the Python API so the compactor uses the
    # model default-compatible temperature while preserving the requested model.
    agent = HaloAgentConfig(
        name="root",
        model=ModelConfig(name=HALO_MODEL),
        maximum_turns=20,
    )
    config = EngineConfig(
        root_agent=agent,
        subagent=agent.model_copy(update={"name": "sub"}),
        synthesis_model=ModelConfig(name=HALO_MODEL),
        compaction_model=ModelConfig(name=HALO_MODEL, temperature=1.0),
        maximum_depth=1,
        maximum_parallel_subagents=2,
    )

    # The notebook already exports the SDK traces locally; HALO does not need
    # hosted trace ingestion for this diagnosis pass.
    set_trace_processors([])

    deltas: list[str] = []
    final_items: list[str] = []
    messages = [AgentMessage(role="user", content=render_halo_prompt())]

    # This pass only needs HALO's trace-analysis tools. Skip the optional
    # `run_code` sandbox so readers do not need a separate Deno/Pyodide setup
    # just to generate the optimization report.
    async def report_progress(done: asyncio.Event, interval_seconds: int = 30) -> None:
        started = time.perf_counter()
        print("HALO optimization started. This is usually the longest cell in the notebook.")
        while not done.is_set():
            try:
                await asyncio.wait_for(done.wait(), timeout=interval_seconds)
            except TimeoutError:
                print(f"HALO still running... {format_duration(time.perf_counter() - started)} elapsed")

    original_sandbox_get = Sandbox.__dict__["get"]
    Sandbox.get = classmethod(lambda cls: None)
    halo_started = time.perf_counter()
    progress_done = asyncio.Event()
    progress_task = asyncio.create_task(report_progress(progress_done))
    try:
        async for event in stream_engine_async(messages, config, context_path):
            if isinstance(event, AgentTextDelta):
                deltas.append(event.text_delta)
            elif isinstance(event, AgentOutputItem) and event.final:
                final_items.append(str(event.item))
    finally:
        progress_done.set()
        await progress_task
        Sandbox.get = original_sandbox_get

    print(f"HALO optimization completed in {format_duration(time.perf_counter() - halo_started)}")
    report = "".join(deltas).strip() or "\n\n".join(final_items).strip()
    if not report:
        raise RuntimeError("HALO completed without producing a report.")
    return report


def clean_halo_handoff(report: str) -> str:
    """Keep only the final Codex-facing handoff sections from HALO output."""
    normalized = re.sub(r"(?<!\n)(## Executive summary)", r"\n\n\1", report).strip()
    start = normalized.rfind("## Executive summary")
    if start == -1:
        raise ValueError("HALO output did not include the expected executive summary section.")

    handoff = normalized[start:].strip()
    required_headings = [
        "## Executive summary",
        "## Top 3 changes to implement first",
        "## Ranked recommendation table",
        "## Supporting diagnosis and evidence",
        "## Detailed recommendations",
        "## Insights by feedback source",
        "## Machine-readable summary",
    ]
    missing = [heading for heading in required_headings if heading not in handoff]
    if missing:
        raise ValueError(f"HALO handoff is missing required sections: {missing}")
    return handoff


def write_halo_handoff(report: str, path: str | Path) -> Path:
    target = Path(path)
    if not target.is_absolute():
        target = PROJECT_ROOT / target
    target.parent.mkdir(parents=True, exist_ok=True)
    target.write_text(report.rstrip() + "\n", encoding="utf-8")
    return target


halo_context = build_halo_context(traces, human_feedback, llm_feedback, eval_suite, gate_result, agent_config)
display(Markdown(halo_input_summary(halo_context)))
halo_context_path = write_halo_optimization_context(halo_context)
halo_report = await run_halo_optimization(halo_context_path)
clean_handoff = clean_halo_handoff(halo_report)

handoff_path = write_halo_handoff(clean_handoff, ARTIFACT_DIR / "codex_handoff.md")

def extract_named_section(report: str, heading: str) -> str:
    if heading not in report:
        return ""
    start = report.index(heading)
    remainder = report[start + len(heading):]
    next_section = re.search(r"\n## ", remainder)
    return report[start:] if next_section is None else report[start:start + len(heading) + next_section.start()]


def render_notebook_halo_summary(report: str) -> str:
    sections = [
        extract_named_section(report, "## Top 3 changes to implement first"),
        extract_named_section(report, "## Insights by feedback source"),
    ]
    rendered = "\n\n".join(section.strip() for section in sections if section.strip())
    return rendered or report


print("Gate result passed into optimization context:", "gate_result" in halo_context)
print("Wrote:")
print("-", halo_context_path.relative_to(PROJECT_ROOT))
print("-", handoff_path.relative_to(PROJECT_ROOT))
步骤 8. 将完整报告交给 Codex
HALO 负责诊断和排序。编码代理或人类仍然需要修改测试工具。
以下是 Codex 可以依据的完整报告快照:前三条建议以及每个反馈来源的简要总结。完整的 codex_handoff.md 文件还包括排序后的更改、支持证据和实现验证指南。
handoff_file = ARTIFACT_DIR / "codex_handoff.md"

if handoff_file.exists():
    print(f"Full Codex handoff written to: {handoff_file.relative_to(PROJECT_ROOT)}")
    print("Snapshot below; open the generated codex_handoff.md file to review the full handoff.")
    display(Markdown(render_notebook_halo_summary(handoff_file.read_text(encoding="utf-8"))))
else:
    print(f"Codex handoff not found yet: {handoff_file.relative_to(PROJECT_ROOT)}")
    print("Run the HALO optimization cell above to generate it.")
步骤 9:闭环
现在完整的工作流已经就绪,我们可以重新审视笔记本开头的优化飞轮。相同的架构支持两种运行模式。
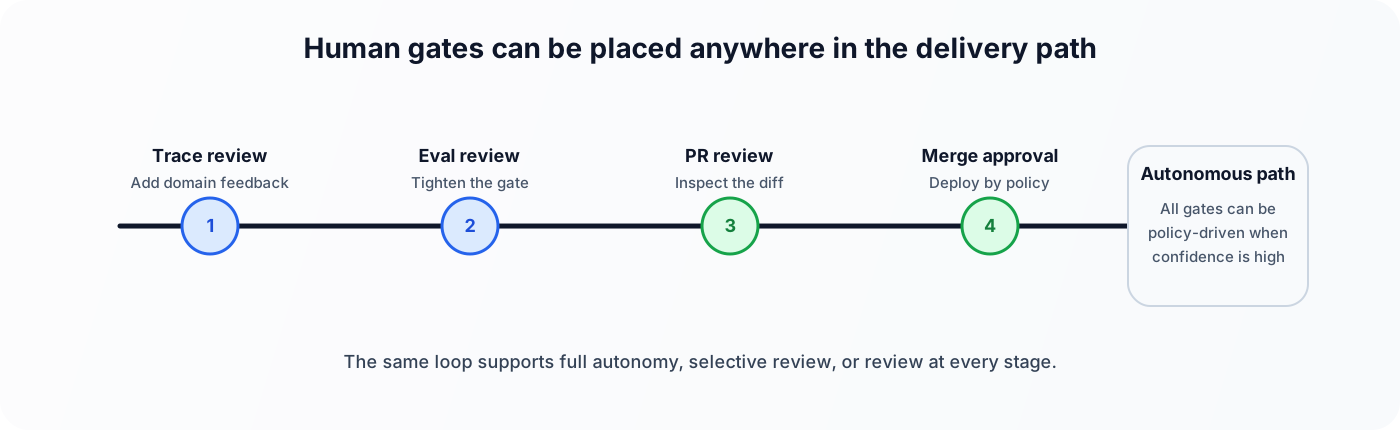 它可以作为闭环运行,其中新的追踪、人工和模型反馈、生成的 Promptfoo 评估、HALO 诊断、Codex 实现、验证和部署都会反馈到下一个循环。在这种模式下,交接工件可以写入共享存储,而带有心跳的 Codex 自动化可以持续检查新的交接,一旦出现就唤醒,并自动触发下一轮实现。
开发者还可以在他们希望的任何地方添加人工门禁,包括追踪审查、评估细化、拉取请求批准、合并和部署。
设计选择在于,在开发者提供反馈后,人类参与的程度如何。人类判断可以引导一个由代理执行任务的循环,或者人类可以在整个过程中保持审批门禁。在这两种版本中,人类反馈都保持核心地位,因为它塑造了系统学习的内容以及接下来要更改的内容。
结论
代理改进循环提供了一条持续改进的路径,而不会将问题简化为仅提示调优。完整的循环至关重要:追踪捕获行为,人类反馈增加判断,评估保留系统应做的内容,HALO 将证据转化为排序的框架变更,而 Codex 可以实施下一轮改进。
这一领域仍在发展,某些单独组件可能会随时间变化。循环工程的更大理念是持久的部分:当反馈、测试和实施在一个循环中连接起来时,代理可以从真实行为中改进。
后续步骤
- 通过编辑笔记本顶部的
AGENT_MODEL、ANALYSIS_MODEL、EVAL_GENERATION_MODEL、JUDGE_MODEL和HALO_MODEL为循环的每个阶段选择模型。 - 创建你自己的跟踪记录来测试代理。
- 决定最终路径中有多少部分应保持人工审查而非自动化:你可以停在开发者审查的 PR 阶段,或者将交接接入一个自动打开、合并和部署更改的系统。
- 将生成的
codex_handoff.md文件(位于ARTIFACT_DIR下)传递给 Codex,检查它提出的 harness 更改,并针对更新后的 harness 重新运行相同的评估套件。
常见问题
常见错误包括:未设置OPENAI_API_KEY导致运行失败;缺少Node.js和npx导致Promptfoo无法运行;模型选择不当导致成本过高或质量下降;追踪导出器配置错误导致HALO无法读取数据;评估生成不准确需人工审查。排查方法:检查环境变量和依赖安装;查看日志和输出文件;验证追踪文件格式;使用更便宜的模型进行测试。生产环境优化:使用缓存减少重复调用;并行化追踪生成;将评估门禁集成到CI/CD;定期审查和更新评估套件。
企业应用扩展
可扩展方向包括:将循环接入自动部署流水线,实现无人值守的智能体改进;增加更多反馈来源,如用户行为数据;使用更复杂的评估方法,如对抗性测试;将HALO优化扩展到多智能体系统;集成其他追踪和可观测性工具。此外,可探索将人工反馈转化为强化学习信号,或使用更先进的优化算法。
总结
本教程面向有编程基础的开发者,深入讲解如何构建一个智能体改进循环。通过一个金融分析师智能体案例,演示了从真实追踪、人工与模型反馈、生成评估到HALO优化和Codex交接的完整流程。教程强调将反馈转化为可复用的评估,并利用证据驱动框架迭代,而非仅依赖提示调优。读者将掌握使用OpenAI Agents SDK、Promptfoo和HALO构建闭环改进系统的方法,并理解各组件间的数据流与设计决策。
- --
内容来源与验证
- 内容等级:PREMIUM_A
- 质量等级:S_CANDIDATE
- 难度:高级
- 验证等级:V1
- 原文作者:PASFIELD-OAI
- 原文日期:2026-05-12
- 来源许可:MIT
- 来源版本:
4dce6d1a299d738a4c6abbd4c9b12d2e7f96246b - 查看原文
站内还有更多完整实战教程
加入会员,解锁全部教程、完整代码与持续更新内容。
加入会员