使用Codex构建迭代修复循环:自动化文档可靠性工作流
技术背景
在AI工程实践中,维护文档、代码示例和配置的准确性是一项耗时且易出错的任务。随着API和SDK的快速迭代,过时的示例会导致开发者困惑,降低产品信任度。传统的人工审查效率低,且难以覆盖所有细节。本文提出的迭代修复循环利用Codex等AI代理,自动执行审查、修复和验证,将人工从重复劳动中解放出来。该技术适用于需要频繁更新且验证标准明确的场景,如API文档、教程、协议草案等。主要限制包括:依赖模型质量、需要明确的验证标准、可能产生额外计算成本。
核心原理
核心原理是闭环代理工作流:代理生成输出(修复),验证输出(执行和评判),并将反馈作为下一轮输入。三个阶段各司其职:审查阶段读取工件,返回结构化发现,不修改文件;修复阶段基于发现和反馈进行针对性编辑;验证阶段运行相关检查(如执行笔记本),并报告剩余问题。关键设计决策包括:使用结构化JSON模式确保阶段间数据可解析;业务规则作为共享契约,聚焦修复方向;验证反馈作为下一轮修复的证据,而非仅依赖初始审查。数据流为:审查发现→修复→验证→反馈→下一轮修复,直至通过或达到停止条件。
架构分析
系统架构分为四个主要组件:1) 业务规则定义模块,提供修复的约束和目标;2) 阶段执行器,包括审查、修复、验证三个独立函数,通过结构化数据交互;3) 迭代控制器,管理多轮循环,支持并发处理多个工件;4) 审计记录模块,保存每轮的record.json,包含审查发现、修复摘要、验证结果和剩余差异。设计思想是模块化、可扩展:每个阶段独立,便于替换或调整;结构化交接使循环可调试、可重跑;并发处理提高效率。关键决策包括:使用Codex CLI无头模式,便于在Python中调用;验证阶段执行笔记本,确保运行时正确性;停止条件包括通过、最大迭代数、差异不变或人工介入。
完整实战教程
使用Codex构建迭代修复循环
本指南介绍闭环代理工作流:代理生成输出、验证输出,并利用反馈改进下一轮迭代。
我们将探索一个文档可靠性工作流,用于检测、修复和验证过时或损坏的API和SDK示例。示例使用了从本Cookbook仓库改编的故意过时的笔记本。
我们将使用Codex构建此代理循环。Codex审查当前状态,应用针对性修改,运行验证,并在反馈显示仍有问题时重复此过程。
笔记本任务仅作为示例。该模式适用于任何代理输出可通过可信反馈衡量的场景。
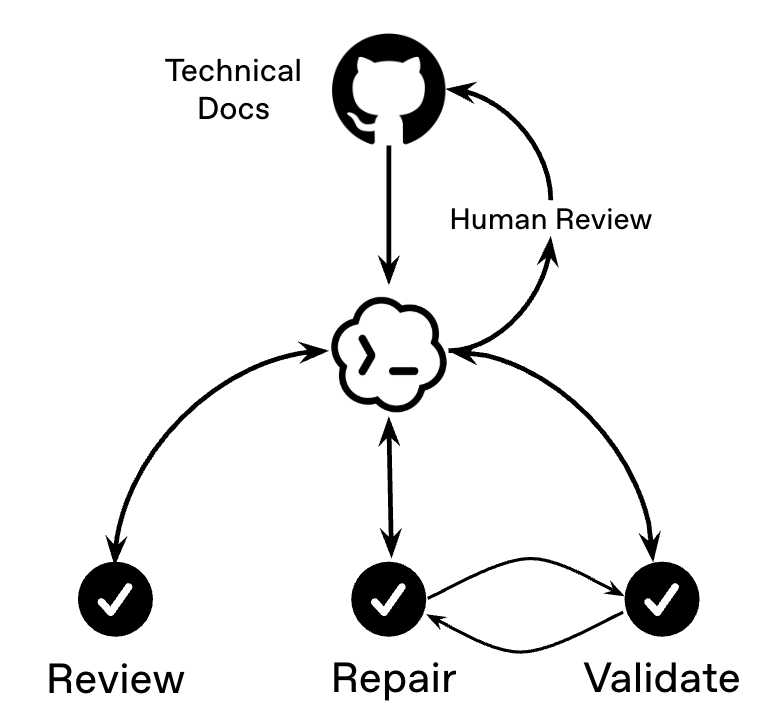
工作流包含三个阶段:
- 审查: 检查当前工件并返回结构化发现,不修改文件。
- 修复: 使用发现和最新验证反馈对复制的工件进行针对性编辑。
- 验证: 运行相关检查并报告仍需改进的内容。
验证闭环。修复后的笔记本必须满足关键检查,任何剩余问题将成为下一轮修复的输入。
<p align="center">
 </p>
设置
本笔记本使用 Codex CLI 的无头模式,因此修复步骤可以在 Python 单元格中运行,而不是在聊天界面中。第一个代码单元格安装 CLI;如果你已经安装了,可以跳过该单元格。
在运行实时修复循环之前,请在环境中设置 OPENAI_API_KEY。
笔记本默认使用快速修复模型,以便完整示例能在合理的时间内完成。要尝试不同的模型,请在开始前设置 REPAIR_MODEL。安装单元格固定了已知的 Codex CLI 版本以确保可重现性;当你想要更新的 CLI 行为时,请有意更新该版本。
!npm install -g @openai/codex@0.130.0
import concurrent.futures
import json
import os
import shlex
import shutil
import subprocess
import tempfile
from pathlib import Path
from typing import Any

CANDIDATE_EXAMPLE_DIRS = [Path("."), Path("examples/codex")]
EXAMPLE_DIR = next((base for base in CANDIDATE_EXAMPLE_DIRS if (base / "data" / "docs").exists()), None)

if EXAMPLE_DIR is None:
    raise RuntimeError(
        "This notebook needs its companion sample notebooks. "
        "Download the data folder that ships with this example and place it next to "
        "this notebook as ./data/docs, or run from a checkout where examples/codex/data/docs exists."
    )

DATA_DIR = EXAMPLE_DIR / "data" / "docs"
DEFAULT_RUNS_DIR = Path(tempfile.gettempdir()) / "codex_iterative_repair_loop_outputs"
RUNS_DIR = Path(os.getenv("CODEX_REPAIR_RUNS_DIR", str(DEFAULT_RUNS_DIR))).expanduser()
RUNS_DIR.mkdir(parents=True, exist_ok=True)
MODEL = os.getenv("REPAIR_MODEL", "gpt-5.4-mini")
COOKBOOK_CHAT_MODEL = os.getenv("COOKBOOK_CHAT_MODEL", "gpt-5.5")
REPAIR_REASONING_EFFORT = os.getenv("REPAIR_REASONING_EFFORT", "low")

if not os.environ.get("OPENAI_API_KEY"):
    raise ValueError("Set the OPENAI_API_KEY environment variable before running the live Codex repair loop.")

CODEX_CLI = shutil.which("codex")
if CODEX_CLI is None:
    raise RuntimeError("Run the install cell before continuing; Codex CLI is not on PATH.")
加载示例工件
下面的单元格加载三个配套笔记本,并总结驱动修复循环的元数据。
这些示例故意做得很小。它们运行很快,但仍然能体现架构:审查发现实质性问题,修复进行有针对性的编辑,验证为下一轮提供反馈。
如果你单独下载此笔记本,也请下载配套的 data/docs/ 文件夹,并将其放在笔记本旁边,然后再运行下面的单元格。代码期望这些示例笔记本在本地可用。
在此示例中,验证会端到端地执行每个修复后的笔记本。在其他领域,验证可能是单元测试、策略检查、模式验证器、模拟或人工审批步骤。重要的是,失败会变成结构化的反馈,而不是死胡同。
NOTEBOOKS = [
    DATA_DIR / "qdrant_embeddings_search_pre_repair.ipynb",
    DATA_DIR / "getting_started_evals_pre_repair.ipynb",
    DATA_DIR / "knowledge_retrieval_pre_repair.ipynb",
]


def read_notebook(path: Path) -> dict[str, Any]:
    return json.loads(path.read_text(encoding="utf-8"))


def case_metadata(path: Path) -> dict[str, Any]:
    return read_notebook(path).get("metadata", {}).get("codex_case_study", {})


cases = []
for notebook_path in NOTEBOOKS:
    notebook = read_notebook(notebook_path)
    metadata = notebook.get("metadata", {}).get("codex_case_study", {})
    repair_story = metadata.get("repair_story", {})
    cases.append(
        {
            "notebook": notebook_path.name,
            "cells": len(notebook["cells"]),
            "code_cells": sum(cell["cell_type"] == "code" for cell in notebook["cells"]),
            "source": metadata.get("source_path"),
            "target_iteration": repair_story.get("target_iteration"),
            "repair_depth": repair_story.get("repair_depth", ""),
        }
    )

cases
定义业务规则和问题分类
在要求 Codex 审查或修复工件之前,给它一个小的共享契约。这能让循环聚焦于重要的问题,而不是要求模型从头推断每个产品和样式规则。
以下规则定义了这些示例笔记本中“好”的含义:当前的 API 模式、清晰的设置、可运行的本地示例,以及保留原始教学目标。在其他工作流中,此契约将描述该领域的真实来源。
business_rules = {
    "preferred_chat_model": COOKBOOK_CHAT_MODEL,
    "preferred_embedding_model": "text-embedding-3-large",
    "modernize": [
        "client.chat.completions.create -> client.responses.create",
        "legacy function-calling schemas -> current tools schema",
        "qdrant.search -> qdrant.query_points",
        "oaieval CLI examples -> current Evals API workflow",
    ],
    "reader_experience": [
        "Make fresh-environment setup explicit.",
        "Keep the included examples runnable with local data and the standard library.",
        "Keep sample repairs self-contained unless the notebook explicitly teaches external setup.",
        "Remove manual result-file placeholders.",
        "State runtime prerequisites and side effects before readers run cells.",
        "Preserve the original teaching goal while modernizing the implementation.",
    ],
}

business_rules
定义结构化输出
每个阶段都返回结构化数据,以便下一阶段有具体的内容可以使用。
审查返回发现。修复返回变更摘要和更新后工件的路径。验证返回下一轮剩余的差异。通过结构化交接,循环更易于调试、重新运行,并适应其他工件类型。
def object_schema(properties: dict[str, Any], required: list[str] | None = None) -> dict[str, Any]:
    return {
        "type": "object",
        "properties": properties,
        "required": required or list(properties),
        "additionalProperties": False,
    }


def string_array() -> dict[str, Any]:
    return {"type": "array", "items": {"type": "string"}}


finding_schema = object_schema(
    {
        "artifact": {"type": "string"},
        "issue_type": {"type": "string"},
        "severity": {"type": "string"},
        "description": {"type": "string"},
        "suggested_fix_direction": {"type": "string"},
    }
)

review_schema = object_schema(
    {"findings": {"type": "array", "items": finding_schema}}
)

fix_schema = object_schema(
    {
        "artifact": {"type": "string"},
        "iteration": {"type": "integer"},
        "changes_made": string_array(),
        "unresolved_items": string_array(),
        "updated_artifact_path": {"type": "string"},
    }
)

validation_case_schema = object_schema(
    {
        "name": {"type": "string"},
        "passed": {"type": "boolean"},
        "severity": {"type": "string"},
        "evidence": {"type": "string"},
        "feedback": {"type": "string"},
    }
)

validation_schema = object_schema(
    {
        "overall_passed": {"type": "boolean"},
        "cases": {"type": "array", "items": validation_case_schema},
        "remaining_delta": string_array(),
    }
)
审查阶段
审查阶段读取产物并返回结构化发现。它不运行验证,也不编辑文件。这种分离使第一步保持专注:在更改任何内容之前识别可能的问题。
我们将审查提示发送给 codex exec,并附带一个 JSON 模式。该模式使结果保持机器可读,因此后续单元格可以直接将发现传递给修复提示,而不是从之前的答案中抓取文本。
def notebook_text(path: Path, max_chars: int = 7000) -> str:
    chunks = []
    for index, cell in enumerate(read_notebook(path)["cells"]):
        source = "".join(cell.get("source", []))
        chunks.append(f"cell {index} ({cell['cell_type']})\n{source}")
    text = "\n\n".join(chunks)
    if len(text) <= max_chars:
        return text
    return text[:max_chars] + "\n\n[truncated for prompt size]"


def run_command(command: str, *, stdin: str | None = None, cwd: Path | None = None, timeout: int | None = None):
    cwd = Path.cwd() if cwd is None else cwd
    return subprocess.run(
        shlex.split(command),
        input=stdin,
        cwd=cwd,
        capture_output=True,
        text=True,
        timeout=timeout,
        check=False,
    )


def run_codex_json(prompt: str, schema: dict[str, Any], run_dir: Path) -> dict[str, Any]:
    run_dir.mkdir(parents=True, exist_ok=True)
    prompt_file = run_dir / "prompt.txt"
    schema_file = run_dir / "schema.json"
    answer_file = run_dir / "answer.json"

    prompt_file.write_text(prompt, encoding="utf-8")
    schema_file.write_text(json.dumps(schema, indent=2), encoding="utf-8")

    command = f"""
    {CODEX_CLI} exec
      --model {MODEL}
      --sandbox workspace-write
      --ask-for-approval never
      --config model_reasoning_effort={REPAIR_REASONING_EFFORT}
      --output-schema {schema_file}
      --output-last-message {answer_file}
      -
    """
    result = run_command(command, stdin=prompt)
    (run_dir / "stdout.txt").write_text(result.stdout, encoding="utf-8")
    (run_dir / "stderr.txt").write_text(result.stderr, encoding="utf-8")

    if result.returncode != 0:
        raise RuntimeError(f"Codex exited with {result.returncode}. See {run_dir / 'stderr.txt'}.")

    return json.loads(answer_file.read_text(encoding="utf-8"))


def review_notebook(path: Path, run_dir: Path) -> list[dict[str, Any]]:
    prompt = "\n".join(
        [
            "You are reviewing a public OpenAI Cookbook notebook before publication.",
            f"Artifact: {path.name}",
            "Find issues that would make the notebook stale, hard to run, or confusing for a developer reader.",
            "Do not execute the notebook or edit files.",
            "Use concise issue_type labels such as stale_model, deprecated_api, setup_gap, runtime_risk, or clarity_issue.",
            f"Business rules: {json.dumps(business_rules)}",
            "Base findings only on the notebook content below.",
            "Keep the findings focused; three strong findings are better than a long list.",
            "",
            notebook_text(path),
        ]
    )
    return run_codex_json(prompt, review_schema, run_dir)["findings"]
def run_initial_review(path: Path) -> tuple[str, list[dict[str, Any]]]:
    return path.name, review_notebook(path, RUNS_DIR / "initial_review" / path.stem)


with concurrent.futures.ThreadPoolExecutor(max_workers=min(3, len(NOTEBOOKS))) as executor:
    initial_reviews = dict(executor.map(run_initial_review, NOTEBOOKS))

initial_reviews
修复阶段
修复阶段获取当前工件、审查发现、业务规则以及上一轮的任何验证反馈。随着循环的学习,提示变得更加具体。
Codex 在迭代目录内的副本上进行编辑,并返回更改的简短摘要。循环不假设编辑成功;验证在下一步中决定这一点。
def repair_prompt(path: Path, updated_path: Path, findings: list[dict[str, Any]], remaining_delta: list[str], iteration: int) -> str:
    repair_story = case_metadata(path).get("repair_story", {})
    return "\n".join(
        [
            "You are repairing a copy of a public OpenAI Cookbook notebook.",
            f"Source notebook: {path}",
            f"Editable copy: {updated_path}",
            f"Iteration: {iteration}",
            "Make the smallest useful edits that address the review findings and validation delta.",
            "Preserve the notebook's teaching flow and original purpose.",
            "Keep sample repairs self-contained unless the notebook explicitly teaches external setup.",
            "For staged examples, focus on the most important remaining issue for this pass instead of rewriting everything at once.",
            "Edit only the editable copy. Do not claim the notebook passes validation.",
            f"Repair depth: {json.dumps(repair_story, indent=2)}",
            f"Business rules: {json.dumps(business_rules, indent=2)}",
            f"Review findings: {json.dumps(findings, indent=2)}",
            f"Remaining validation delta: {json.dumps(remaining_delta, indent=2)}",
        ]
    )


def repair_notebook(path: Path, iteration: int, findings: list[dict[str, Any]], remaining_delta: list[str], case_dir: Path) -> dict[str, Any]:
    updated_path = case_dir / "updated.ipynb"
    updated_path.parent.mkdir(parents=True, exist_ok=True)
    shutil.copy2(path, updated_path)

    prompt = repair_prompt(path, updated_path, findings, remaining_delta, iteration)
    return run_codex_json(prompt, fix_schema, case_dir / "repair")
验证阶段
验证就像一个小型评估。我们定义期望的行为,运行相关检查,并让评判者根据该标准对结果进行评分。
对于文档示例,执行优先。许多笔记本问题只在运行时出现:缺少导入、过时的文件路径、依赖旧 API 响应的单元格,或者对作者清晰但对新读者不明确的设置指南。
如果验证失败,失败将成为下一轮修复的证据。这使下一轮修复基于观察到的行为,而不仅仅是差异中看起来正确的内容。
VALIDATION_CASES = [
    {
        "name": "api_modernization",
        "question": "Does the notebook avoid stale OpenAI API patterns, legacy function-calling syntax, and outdated model names?",
    },
    {
        "name": "setup_reproducibility",
        "question": "Could a reader run the notebook from a fresh environment without hidden manual steps?",
    },
    {
        "name": "artifact_integrity",
        "question": "Did the update preserve the notebook's teaching flow and avoid deleting substantive cells?",
    },
]


def short_output(value: Any, limit: int = 1200) -> str:
    if value is None:
        return ""
    if isinstance(value, bytes):
        value = value.decode("utf-8", errors="replace")
    return str(value)[-limit:]


def execute_notebook(path: Path) -> dict[str, Any]:
    code_cells = sum(cell["cell_type"] == "code" for cell in read_notebook(path)["cells"])
    command = f"jupyter nbconvert --to notebook --execute --inplace {path.name}"

    try:
        result = run_command(
            command,
            cwd=path.parent,
            timeout=int(os.getenv("SAMPLE_NOTEBOOK_TIMEOUT_SECONDS", "300")),
        )
    except FileNotFoundError:
        return {
            "status": "failed",
            "executed_code_cells": 0,
            "error": "Jupyter or nbconvert is not installed or is not available on PATH.",
            "summary": "Install Jupyter with nbconvert before running the validation loop.",
        }
    except subprocess.TimeoutExpired as exc:
        return {
            "status": "failed",
            "executed_code_cells": 0,
            "error": f"Notebook execution timed out after {exc.timeout} seconds.",
            "summary": short_output(exc.stderr or exc.stdout),
        }

    output = result.stderr or result.stdout
    return {
        "status": "passed" if result.returncode == 0 else "failed",
        "executed_code_cells": code_cells if result.returncode == 0 else 0,
        "error": "" if result.returncode == 0 else f"Notebook execution exited with code {result.returncode}.",
        "summary": short_output(output),
    }

def validation_prompt(updated_path: Path, before_path: Path, execution: dict[str, Any], iteration: int) -> str:
    repair_story = case_metadata(before_path).get("repair_story", {})
    return "\n".join(
        [
            "You are judging a repaired OpenAI Cookbook notebook.",
            f"Iteration: {iteration}",
            "Score each validation case independently and give concise feedback for the next repair pass.",
            "Set overall_passed to false when execution failed or any case has a material issue.",
            "When execution failed, include the failure in remaining_delta so the next repair pass can address it.",
            "Use the business rules as the source of truth for current model names and API targets.",
            "Do not mark the preferred embedding model or preferred chat model as stale.",
            "For local examples, do not require extra services or package installs when the notebook says it is intentionally self-contained.",
            f"Repair depth: {json.dumps(repair_story, indent=2)}",
            f"Business rules: {json.dumps(business_rules, indent=2)}",
            f"Validation cases: {json.dumps(VALIDATION_CASES, indent=2)}",
            f"Execution evidence: {json.dumps(execution, indent=2)}",
            f"Original cell count: {len(read_notebook(before_path)['cells'])}",
            f"Updated cell count: {len(read_notebook(updated_path)['cells'])}",
            "",
            notebook_text(updated_path),
        ]
    )


def staged_delta(before_path: Path, iteration: int) -> list[str]:
    repair_story = case_metadata(before_path).get("repair_story", {})
    target = int(repair_story.get("target_iteration") or 1)
    if iteration >= target:
        return []
    depth = repair_story.get("repair_depth", "This case is intentionally staged across multiple repair passes.")
    return [f"Continue to iteration {iteration + 1}: {depth}"]


def evaluate_notebook(updated_path: Path, before_path: Path, run_dir: Path, iteration: int) -> dict[str, Any]:
    execution = execute_notebook(updated_path)
    judged = run_codex_json(validation_prompt(updated_path, before_path, execution, iteration), validation_schema, run_dir)
    failed_cases = [case for case in judged["cases"] if not case["passed"]]
    execution_delta = []
    if execution["status"] != "passed":
        execution_delta.append(f"Execution failed: {execution.get('error') or execution.get('summary')}")

    stage_delta = staged_delta(before_path, iteration)
    return {
        "passed": judged["overall_passed"] and execution["status"] == "passed" and not stage_delta,
        "execution_status": execution["status"],
        "executed_code_cells": execution["executed_code_cells"],
        "execution_summary": execution["summary"],
        "findings": failed_cases,
        "remaining_delta": execution_delta + stage_delta + judged["remaining_delta"],
    }
保存每次迭代的输出
每次迭代都会写入一个 record.json 文件,并且在此示例中,还会在 CODEX_REPAIR_RUNS_DIR/iteration_N/<sample_name>/ 下写入一个修复后的笔记本。如果你没有设置 CODEX_REPAIR_RUNS_DIR,笔记本会写入系统临时目录,这样正常的仓库检出保持干净。
这些文件就是审计跟踪。你可以看到审查发现了什么、Codex 更改了什么、执行是否通过,以及哪些反馈进入了下一次迭代。
record.json 文件是一次循环尝试的收据。它将各阶段之间的交接保存在一个地方:
{
"review": [{"issue_type": "deprecated_api", "severity": "high"}],
"repair": {
"changes_made": ["Updated the notebook to use the current API pattern."],
"updated_artifact_path": "/tmp/codex_iterative_repair_loop_outputs/iteration_1/sample/updated.ipynb"
},
"validation": {
"passed": false,
"remaining_delta": ["One setup instruction is still unclear."]
}
}
这种紧凑的记录让维护者无需从笔记本差异和终端日志中重建整个运行过程,就能审查循环。
def save_json(payload: Any, path: Path) -> None:
    path.parent.mkdir(parents=True, exist_ok=True)
    path.write_text(json.dumps(payload, indent=2) + "\n", encoding="utf-8")


def iteration_dir(number: int) -> Path:
    path = RUNS_DIR / f"iteration_{number}"
    path.mkdir(parents=True, exist_ok=True)
    return path
运行迭代 1
每个笔记本案例都是独立的,因此我们并发处理这些案例。这既保持了演示的速度,又对每个样本保留了相同的审查、修复和验证流程。
迭代 1 复用了先前审查单元格中的初始审查结果。此轮过后,检查返回的布尔值:通过的案例可以停止,未通过的案例则将其验证反馈带入下一轮。
current_notebooks = {path.name: path for path in NOTEBOOKS}
history: dict[int, dict[str, Any]] = {}


def review_findings_for(original: Path, current_path: Path, case_dir: Path, previous_results: dict[str, Any] | None) -> list[dict[str, Any]]:
    if previous_results is None:
        return initial_reviews[original.name]
    return review_notebook(current_path, case_dir / "review")


def run_case(number: int, original: Path, run_dir: Path, previous_results: dict[str, Any] | None) -> tuple[str, dict[str, Any], Path]:
    name = original.name
    case_dir = run_dir / original.stem
    current_path = current_notebooks[name]

    findings = review_findings_for(original, current_path, case_dir, previous_results)
    delta = [] if previous_results is None else previous_results[name]["validation"]["remaining_delta"]
    repair = repair_notebook(current_path, number, findings, delta, case_dir)
    updated_path = Path(repair["updated_artifact_path"])
    validation = evaluate_notebook(updated_path, current_path, case_dir / "evaluation", number)

    record = {"review": findings, "repair": repair, "validation": validation}
    save_json(record, case_dir / "record.json")
    return name, record, updated_path


def run_iteration(number: int, previous_results: dict[str, Any] | None = None) -> dict[str, Any]:
    results = {}
    updates = {}
    run_dir = iteration_dir(number)

    with concurrent.futures.ThreadPoolExecutor(max_workers=min(3, len(NOTEBOOKS))) as executor:
        futures = [executor.submit(run_case, number, original, run_dir, previous_results) for original in NOTEBOOKS]
        for future in concurrent.futures.as_completed(futures):
            name, record, updated_path = future.result()
            results[name] = record
            updates[name] = updated_path

    current_notebooks.update(updates)
    history[number] = results
    return results


iteration_1 = run_iteration(1)
{name: result["validation"]["passed"] for name, result in iteration_1.items()}
运行迭代 2
迭代 2 是循环开始产生回报的地方。Codex 不再仅仅根据最初的审查来工作;它还会看到验证期间发生的情况。
这改变了任务。我们不再要求进行广泛的改写,而是根据上次运行的证据请求下一个有用的修复:哪些执行了,哪些通过了,哪些仍需要关注。
对于包含的分阶段测试夹具,此过程旨在清除中等深度的 Evals 案例,而更深的 Knowledge Retrieval 案例则继续使用更小、更具体的增量。
iteration_2 = run_iteration(2, iteration_1)
{name: result["validation"]["passed"] for name, result in iteration_2.items()}
运行迭代 3
迭代 3 聚焦于最深入的文档案例。
知识检索夹具必须现代化 API 形态,保持本地数据可运行,并保留检索教学流程。这些要求可能会相互冲突:使 notebook 现代化的修复可能会意外地降低其可运行性,而保持本地化的修复可能会移除过多原始课程内容。
第三遍给 Codex 最新的 notebook 加上最终的验证增量。这是演示中展示迭代重要性的部分:代理针对剩余的具体问题做出响应,而不是试图预先预测所有问题。
iteration_3 = run_iteration(3, iteration_2)
{name: result["validation"]["passed"] for name, result in iteration_3.items()}
总结改进
现在我们可以查看整个运行过程,而不必手动打开每个中间产物。下面的总结显示了最重要的信号:哪些产物通过了,还有多少验证发现,以及是否有任何差异被延续。
对于包含的测试夹具,预期的形状很简单:一个笔记本在第一次迭代中清除,另一个在第二次迭代中清除,最深的一个在第三次迭代中清除。在实际的维护工作流中,此表告诉您循环是否正在收敛,或者是否需要更清晰的约束或人工审查。
此总结对于人工审查也很有用。维护者可以从通过/失败模式开始,打开仍有差异的记录,并仅检查已修复且准备审查的产物。
summary = []
for iteration, results in history.items():
    for artifact, record in results.items():
        validation = record["validation"]
        summary.append(
            {
                "iteration": iteration,
                "artifact": artifact,
                "passed": validation["passed"],
                "findings": len(validation["findings"]),
                "remaining_delta": len(validation["remaining_delta"]),
            }
        )

summary
for row in summary:
    print(
        f"iteration={row['iteration']} artifact={row['artifact']} "
        f"passed={row['passed']} findings={row['findings']} delta={row['remaining_delta']}"
    )
摘要告诉了我们什么
重要的信号不是 Codex 进行了编辑。重要的信号是,随着循环的运行,剩余的验证差异越来越小。
| 轮次 | 要寻找的信号 | 为什么重要 |
| --- | --- | --- |
| 迭代 1 | 最简单的测试通过;更深入的测试保持较小的差异。 | 循环可以进行初步修复,同时保留仍需证据的案例。 |
| 迭代 2 | 中等深度的测试在收到验证反馈后通过。 | 运行时和评判反馈成为有用的修复指令。 |
| 迭代 3 | 最深的测试通过或留下一个集中的最终差异。 | 循环收敛,或者为人工审查者提供清晰的交接。 |
record.json 文件是使这变得可审计的地方。有用的记录回答了四个问题:审查发现了什么,Codex 更改了什么,笔记本是否执行,以及还剩下什么?这就是一个令人印象深刻的编辑与维护者可以信任的修复工作流之间的区别。
泛化为连续循环
上面固定的三轮运行对于教学模式很有用。生产环境中的循环应该自行决定何时停止。
一个好的循环通常因以下四个原因之一而停止:验证通过、循环达到最大尝试次数、剩余差异不再变化,或者下一个决策需要人工审查。这些停止条件与修复提示同样重要。
另一个生产细节是审计跟踪。保留每一轮的审查发现、修复后的工件、验证结果、验证判断和剩余差异。这些记录能让维护者理解循环为何继续、为何停止,以及哪个工件可以进入审查。
def repair_until_done(max_iterations: int = 3) -> dict[int, dict[str, Any]]:
    current_notebooks.update({path.name: path for path in NOTEBOOKS})
    previous = None
    loop_history = {}

    for number in range(1, max_iterations + 1):
        previous = run_iteration(number, previous)
        loop_history[number] = previous
        if all(record["validation"]["passed"] for record in previous.values()):
            break

    return loop_history
这还适用于哪些场景
笔记本演练只是教授架构的一种方式。每当代理修改的文件或流程需要超出主观审查的更多验证才能被接受时,同样的模式也会有所帮助。
几个高价值的示例:
- 协议优化: 起草更新供专家审查,然后根据剂量规则、时间限制或必需的安全检查进行验证。
- 法规整改: 起草受监管内容的更新,然后检查必需的语言、引用、批准和特定司法管辖区的条款是否保持完整。
- 支持知识更新: 更新文章,根据当前产品行为或已知解决方案进行测试,并将不匹配之处带入下一轮。
- 代码现代化: 替换已弃用的 API,运行测试或静态检查,并利用剩余的失败来指导下一次修复。
共同点是变更很重要,并且每一轮都需要证据。无论目标是笔记本、政策、协议、支持文章、管道还是代码库,这个循环都为代理提供了一种改进它的方法,并附有维护者可以审查的证据。
结论
迭代修复循环使代理维护更易于审查和操作,因为它们将判断与证明分离。
审查发现候选问题。修复进行有针对性的编辑。验证执行工件并产生下一个增量。当这些阶段交换结构化输出时,工作流变得更容易检查、重复和适应。
主要思想很简单:不要依赖单次通过,而是给工作流一种从工件中学习、进行有限修复并对真实验证反馈做出反应的方式。这一小改动使代理维护变得更加实用。
常见问题
常见错误:1) 未设置OPENAI_API_KEY,导致Codex调用失败,需在环境变量中配置。2) Codex CLI未安装或版本不匹配,需运行安装单元格并固定版本。3) 缺少配套数据文件夹,导致示例笔记本无法加载,需下载data/docs并放置正确位置。4) 验证阶段执行笔记本超时,可调整SAMPLE_NOTEBOOK_TIMEOUT_SECONDS。5) 模型输出不符合JSON schema,导致解析失败,可检查prompt和schema定义。排查方法:查看run_dir下的stdout.txt和stderr.txt,检查Codex退出码;检查record.json中的验证反馈。生产优化:使用更强大的模型(如gpt-5.5)提高修复质量;增加验证用例覆盖更多场景;实现动态停止条件,避免无效迭代;并行处理多个工件,提高吞吐量。
企业应用扩展
该模式可扩展到其他领域:1) 代码现代化:自动替换弃用API,运行测试验证。2) 协议优化:起草更新,根据规则验证。3) 法规整改:检查必需语言和引用。4) 支持知识更新:根据产品行为测试文章。扩展时需定义明确的验证标准,并确保反馈结构化。可改进点包括:引入人工审批环节,在关键决策时暂停;使用强化学习优化修复策略;集成CI/CD,自动触发修复循环。
总结
本文介绍如何利用OpenAI Codex构建闭环代理工作流,自动检测、修复并验证过时的API和SDK示例。通过审查、修复、验证三阶段循环,代理生成输出、验证输出,并利用反馈改进下一轮迭代。文章以文档可靠性为例,展示如何将业务规则、结构化输出和验证反馈结合,实现可审计的自动化修复。该模式适用于代码现代化、协议优化、法规整改等场景,核心在于将判断与证明分离,让代理基于证据持续改进。
- --
内容来源与验证
- 内容等级:PREMIUM_A
- 质量等级:S_CANDIDATE
- 难度:中级
- 验证等级:V1
- 原文作者:shreekant-openai
- 原文日期:2026-05-11
- 来源许可:MIT
- 来源版本:
f062900c70aae09a2048236f5ef3e94d6ff54db5 - 查看原文
站内还有更多完整实战教程
加入会员,解锁全部教程、完整代码与持续更新内容。
加入会员